Blog

  • Traceability in Aerospace: Why Retrofitting Always Fails

    Traceability in Aerospace: Why Retrofitting Always Fails

    Traceability in Aerospace: Why Retrofitting Always Fails

    Across aerospace manufacturing, many organizations still treat traceability as something that can be reconstructed when needed. Batches, serials, inspection records, and signoffs live in ERP, on paper travelers, in shared folders, and in email. When a customer, regulator, or OEM asks for proof, a small army goes hunting for it.

    That pattern works—until it doesn’t. As programs mature, requirements tighten, and suppliers move up the value chain, retrofit traceability becomes a structural liability. It burns time, hides risk, and fails precisely when the stakes are highest. In a world where aerospace success is defined by execution, not surface metrics, treating traceability as an after-the-fact documentation exercise is no longer viable.

    For teams putting this topic into daily operation, Connect 981’s aerospace execution solutions help connect the concept to traceability, work-order reality, and audit-ready evidence.

    For teams putting this topic into daily operation, execution systems for aerospace manufacturing, part traceability and as-built evidence help connect the concept to traceability, work-order reality, and audit-ready evidence.

    The same operating model also depends on shop floor execution control, a connected execution platform, Connect 981’s aerospace operations guidance, practical aerospace operations FAQs, especially when decisions have to move across quality, production, suppliers, and program leadership without losing context.

    This article explains what aerospace traceability really entails, why retrofit models break under pressure, and how to design an execution layer where part genealogy, material lots, and inspection records emerge naturally from the way work is done.

    What Aerospace Traceability Really Entails

    Traceability in aerospace is often summarized as “know which parts went where.” In practice, it is a dense web of relationships that must be reconstructed quickly and confidently under audit conditions or when non-conformances surface.

    Part genealogy from raw material to finished assembly

    At the core is part genealogy: the ability to follow every serialized or lot-controlled item from raw material through intermediate stages to final assembly or shipset. For a typical structure or engine component, this may include:

    • Raw material heat, cast, or lot numbers and mill certifications
    • Conversion steps such as forging, extrusion, or casting, including supplier work orders
    • Intermediate part numbers and revisions as the design evolves
    • Assembly relationships (which serialized subassemblies are installed on which top-level unit)
    • Repair, rework, or concession paths where the original routing was not followed

    Genealogy is not just a static list of serial numbers. It is a time-ordered, configuration-aware history of how each item moved through the product and process.

    Linking individuals, equipment, and processes to outcomes

    Regulators and OEMs increasingly expect more than “this part came from that lot.” They want to know how it was produced:

    • Which operators or technicians executed each operation
    • Which machines, test stands, or fixtures were used (with their calibration status)
    • Which specific work instructions and revisions were followed
    • Which process parameters were controlled and recorded for special processes
    • Which inspections, measurements, and test procedures were performed and by whom

    These links are crucial when analyzing systemic issues. Without them, it is impossible to distinguish between an isolated operator error and a deeper process capability or design problem.

    Supporting AS9100, FAA/EASA, and customer-specific requirements

    Standards like AS9100, aviation authorities such as the FAA and EASA, and major OEMs all impose overlapping but distinct traceability expectations. Common themes include:

    • Evidence that only approved, conforming material and components were used
    • Documented control of special processes, including qualification and periodic verification
    • Configuration control of design data, work instructions, and inspection plans
    • Retention of records for long periods, often tied to product life or regulatory mandates

    Critically, these rules do not just demand that records exist; they require that records be complete, consistent, and accessible. That requirement is what makes retrofit approaches so fragile.

    The Retrofitting Pattern—and Its Failure Modes

    Retrofit traceability is the pattern where records are scattered across systems and formats, and only stitched together after the fact when triggered by an event. It is common because it evolves organically: new forms are added, new spreadsheets appear, and nobody has time to redesign the flow.

    Spreadsheet-based reconstruction after non-conformances or incidents

    The most visible symptom of retrofit traceability is the “trace spreadsheet” that appears during a non-conformance investigation or customer request. A quality engineer or program manager:

    • Pulls shipment data from ERP
    • Requests paper travelers from production or archives
    • Collects supplier certificates via email
    • Copies measurement data from lab systems or PDFs
    • Builds a pivot table that approximates genealogy

    This can work for isolated events. But it does not scale as production volume, program count, or traceability depth increase. Every reconstruction is a small project, and every project competes with real production work.

    Chasing paper travelers and manual logs across departments

    Another hallmark of retrofit traceability is reliance on paper travelers and local logs. Typical issues include:

    • Travelers filed by work order rather than by serial number, forcing manual cross-references
    • Handwritten inspection results that are difficult to read or incomplete
    • Logbooks maintained on individual machines with no central index
    • Signoffs recorded as initials without unambiguous linkage to people, roles, or qualifications

    When a customer asks which units are affected by a suspect material lot or process parameter drift, each department becomes a search team. The response time is long, the uncertainty is high, and leadership’s confidence in the data degrades.

    Time, cost, and risk when evidence is incomplete or inconsistent

    The most serious failure mode is not the time spent searching—it is incomplete evidence. Missing travelers, unsigned inspections, mismatched serial numbers, or ambiguous part revisions can force conservative decisions:

    • Scrapping or reworking hardware that might be acceptable, because proof is not available
    • Extending the scope of an inspection or recall beyond what is actually affected
    • Accepting higher risk than desired under schedule or contractual pressure

    These outcomes are expensive in terms of cost, schedule, and trust. They are also completely predictable when genealogy and records are bolted on rather than built in.

    Where Traditional Systems Fall Short on Traceability

    Most aerospace organizations already have several core systems—ERP, some form of MES or production tracking, and a quality management system. The issue is not the absence of systems; it is their misalignment with how traceability actually works in a regulated production environment.

    ERP’s limited granularity for lot and serial tracking

    ERP is optimized for planning and commercial control, not detailed execution. It can track lot and serial numbers at receipt and shipment, and sometimes at key routing steps. But it typically lacks:

    • Fine-grained event history at the operation level
    • Visibility into partial completions, rework loops, or out-of-sequence work
    • Direct linkage to actual work instructions, drawings, and inspection plans used at each step
    • Operator- and equipment-level trace at the resolution regulators increasingly expect

    Using ERP alone to support aerospace traceability usually means pushing it beyond its intended scope and filling gaps with spreadsheets and emails.

    MES implementations that don’t fully cover manual operations

    Many plants have an MES or shop-floor system, often implemented around automated equipment or tightly defined routings. But manual and low-volume work—common in aerospace—frequently sits outside that footprint:

    • Bench assembly, kitting, or hand fitting done on generic workstations
    • Manual inspections recorded on paper checklists
    • Special processes performed at qualified suppliers with their own systems

    This creates blind spots where work is real but data is thin. If genealogy depends on MES where it exists and paper where it doesn’t, traceability is only as strong as the weakest segment of the flow.

    Quality systems not tightly linked to actual execution steps

    Quality management tools handle non-conformances, corrective actions, and audits, but often reside at arm’s length from day-to-day production. Typical gaps include:

    • Non-conformances logged against part numbers or work orders without direct linkage to the exact operation, instruction, or operator
    • Inspection plans managed separately from the work instructions they are supposed to verify
    • Calibration and special process qualification records not directly tied to the lots or serials they affect

    Without a tight connection between quality events and execution data, root cause analysis becomes slower, and corrective actions risk being generic rather than targeted.

    Principles of Embedded Traceability

    Embedded traceability is the opposite of retrofit traceability. Instead of assembling evidence after the fact, you design your execution layer so that compliant records emerge automatically as a byproduct of doing the work correctly.

    Capturing data at the point and moment of work

    The first principle is simple but difficult to achieve: capture data where and when work occurs. That means:

    • Operators record completion and signoff at the station, not later at a desk
    • Measurements are logged directly into a digital form linked to the operation, not onto paper to be typed in later
    • Deviations, holds, and concessions are created in context of the specific part, operation, and revision

    Point-of-work capture dramatically reduces transcription errors and missing records. It also improves data richness—timestamps, user identity, and real process context are automatically included.

    Minimizing duplicate entry and manual logging

    Operators and inspectors will work around any system that adds friction without value. Embedded traceability succeeds only if it makes the right thing the easy thing. Design considerations include:

    • Single source of truth for work instructions and inspection plans, surfaced through the same interface used to record completion
    • Automatic pull of part, lot, and configuration information from upstream systems rather than re-keying IDs
    • Barcode or RFID scanning for material and tool identification where practical
    • Smart defaults and validation that prevent incomplete or inconsistent entries

    The target state is a workflow where operators do less clerical work than before, yet you gain better traceability than you had with paper and spreadsheets.

    Maintaining configuration context for each operation

    In aerospace, the same part number can exist across multiple configurations and revisions. Embedded traceability must respect that reality:

    • Every execution event is tied to a specific configuration: part revision, bill of material version, and approved process plan
    • Digital work instructions and inspection criteria are revision-controlled and linked directly into the execution step
    • Changes in design or process trigger controlled transitions in how work is performed and recorded

    This configuration awareness is the bridge between the digital thread (engineering and planning data) and the actual work on the shop floor. Without it, genealogy might be complete in terms of serials but misleading in terms of what was actually built.

    Execution Layer Capabilities for Traceability

    To make embedded traceability real, you need an execution layer that sits between planning systems and the physical work. This layer is not just a digital traveler; it is the environment where work instructions, materials, people, and quality controls are bound together in real time.

    Binding work instructions, parts, and materials together

    A capable execution layer should:

    • Present the right work instructions and inspection criteria based on part, configuration, and routing step
    • Associate each operation completion with specific material lots, subcomponents, and tooling where required
    • Enforce material and component validity (e.g., block use of expired materials or unapproved alternates)

    When this binding is handled digitally, genealogy becomes an automatic output: you can traverse from a serial number to all contributing lots and process steps without manual reconstruction.

    Recording operator actions, inspections, and deviations

    In an embedded model, every significant execution event is captured as structured data:

    • Operator logins and qualifications verified at signoff
    • Complete lists of steps performed, with timestamps and status
    • Measured values, pass/fail results, and inspection outcomes tied to specific characteristics
    • Deviations, holds, and non-conformances linked directly to the affected parts and operations

    This level of detail is essential when demonstrating control to OEMs and regulators, and when diagnosing the root cause of escapes or process instability.

    Automatically generating genealogy and as-built records

    When the execution layer continuously captures events, as-built records no longer require their own dedicated project. They can be generated on demand from the event history:

    • Unit-level build records for each aircraft or spaceflight hardware item
    • Consolidated view of all special processes, tests, and inspections applied
    • Forward and backward trace queries (from material lot to affected units, and from unit to contributing materials and processes)

    This is where traceability shifts from being a cost center to an asset. The same data used for compliance also supports process improvement, yield analysis, and design feedback.

    Traceability Across the Aerospace Supply Chain

    Aerospace traceability does not stop at the walls of a single plant. OEMs, tier-1s, and lower-tier suppliers are all part of a shared genealogy that must hold together under audit and in-service events.

    Ensuring lot-level continuity between OEMs and suppliers

    For many suppliers, traceability demands originate in flowdowns from OEM contracts. Common challenges include:

    • Receiving material with partial or inconsistent certifications from upstream suppliers
    • Splitting and combining lots across multiple work orders and customers
    • Reporting trace data back to OEMs in their required formats

    Embedded traceability in the supplier’s execution layer makes it far easier to maintain continuity: incoming certs are captured once, lot splits are recorded digitally, and outgoing documentation can be generated directly from internal records rather than rebuilt in spreadsheets.

    Managing special processes and certifications

    Special processes (heat treatment, welding, non-destructive testing, coatings) are often performed by external specialists or dedicated in-house cells. Their traceability burden is high because failures are difficult to detect downstream. Effective control requires:

    • Clear linkage between each special process event and the certified procedure, equipment, and personnel
    • Evidence that periodic qualifications and calibrations were in force at the time of work
    • Integration between special process records and downstream assembly and test steps

    When special-process data is captured in isolation, traceability across the product’s life becomes brittle. An execution layer that includes or connects to these processes reduces that brittleness dramatically.

    Handling returns, rework, and MRO traceability extensions

    Aircraft, engines, and space systems live for decades. Maintenance, repair, and overhaul (MRO) work must extend the original genealogy instead of restarting it. Challenges include:

    • Linking returned units back to their original as-built records
    • Recording rework, part replacements, and configuration changes performed during service
    • Ensuring that MRO trace data is compatible with OEM and authority expectations

    Execution-layer traceability makes it possible to maintain a continuous view of each unit’s life, spanning original manufacture and all subsequent interventions.

    Moving from Retrofit to Embedded: A Transition Approach

    Most organizations cannot stop production and redesign their traceability model from scratch. The path from retrofit to embedded traceability needs to be incremental, risk-based, and tightly aligned with ongoing operations.

    Identifying high-risk products and processes first

    An effective transition starts with a clear prioritization:

    • Flight-critical or safety-critical hardware with strict regulatory oversight
    • Programs with frequent customer audits or known traceability gaps
    • Processes with high rework rates or recurring non-conformances

    By focusing digital traceability on these hotspots first, organizations can demonstrate value quickly while reducing their most significant compliance and quality risks.

    Digitizing travelers and inspection forms incrementally

    Instead of rebuilding every routing at once, many teams start by digitizing existing travelers and forms with minimal structural changes:

    • Convert paper travelers into electronic travelers that mirror current steps
    • Replace paper inspection sheets with digital checklists linked to operations
    • Add barcode or QR codes to connect physical parts and documents to digital records

    Once operators are comfortable with digital capture, you can iteratively refine workflows, add configuration logic, and deepen integration with upstream engineering data.

    Leveraging platforms like Connect 981 for shared traceability

    Platforms such as Connect 981 are designed to operate as the connective tissue between planning systems and real-world execution. In the context of traceability, that means:

    • Providing a shared execution layer that surfaces the right work instructions and captures events as work happens
    • Integrating with ERP, PLM, and quality systems so genealogy reflects both engineering intent and shop-floor reality
    • Supporting supplier participation in a common traceability framework, rather than exchanging static documents alone

    This kind of execution infrastructure aligns directly with the broader shift described in the analysis of why traditional aerospace scoreboards miss what actually matters. When traceability is embedded in the execution layer, audit readiness becomes a byproduct of production, not a separate project triggered by bad news.

    From Documentation Burden to Operational Asset

    Retrofitted traceability treats records as a necessary burden, assembled only when someone asks for proof. Embedded traceability reframes those same records as a live, operational asset: a precise picture of how each unit was built, by whom, with what materials, and under which controls.

    For aerospace manufacturers, the choice is no longer between more paperwork or less. The real decision is whether to continue paying the hidden cost of reconstruction and uncertainty, or to invest in an execution layer where compliance, quality, and operational insight are created simultaneously at the point of work.

  • Building Resilient Aerospace Supplier Networks Through Connected Execution

    Building Resilient Aerospace Supplier Networks Through Connected Execution

    Aerospace supply chain resilience is usually discussed in terms of contracts, dual-sourcing, and inventory buffers. Those levers matter, but they ignore where many disruptions actually start: inside supplier factories, in the invisible gap between the production plan and what is really happening on the line. In a network built on complex, regulated work, resilience is fundamentally an execution problem.

    This is the same pattern explored in the broader pattern behind OEM scoreboard narratives: top-level KPIs and scorecards hide the operational reality that determines whether programs stay stable under stress. In the supply base, that reality lives in how work is sequenced, controlled, and recovered when something goes wrong.

    For teams putting this topic into daily operation, Connect 981’s aerospace execution solutions help connect the concept to traceability, work-order reality, and audit-ready evidence.

    For teams putting this topic into daily operation, execution systems for aerospace manufacturing, supply chain and supplier execution help connect the concept to traceability, work-order reality, and audit-ready evidence.

    The same operating model also depends on shop floor execution control, a connected execution platform, Connect 981’s aerospace operations guidance, practical aerospace operations FAQs, especially when decisions have to move across quality, production, suppliers, and program leadership without losing context.

    Looking at aerospace supply chain resilience through an execution lens changes the conversation. Instead of asking, “Do we have a second source?” the better questions are, “Can we see what is really happening at critical suppliers?” and “Can we coordinate response before problems become surprises?” This article unpacks how execution gaps at tier-1 and tier-2 suppliers drive risk, and how a shared execution layer can turn fragile networks into collaborative, predictable systems.

    Why Traditional Views of Aerospace Supply Chain Resilience Are Incomplete

    Focus on contracts, capacity, and inventory buffers

    Most resilience discussions start with three themes: long-term contracts, nominal capacity, and inventory. OEMs negotiate volume and price for years ahead, ask suppliers to demonstrate capacity, and create safety stocks of long-lead items or critical assemblies. Risk registers and mitigation plans often sit at this level.

    Those tools help with strategic risk, but they operate at a coarse resolution. A supplier might show a nameplate capacity of 20 shipsets per month, yet struggle to produce more than 14 without chronic overtime, rework, and schedule churn. A contract may secure capacity on paper but says nothing about whether the supplier’s day-to-day execution system can handle a surge, a configuration change, or a new surveillance requirement.

    Inventory buffers can buy time, but in aerospace they are expensive, regulated, and often constrained by configuration and effectivity. When the underlying execution system is unstable, inventory becomes a band-aid that slowly erodes under variability, leaving OEMs surprised when the buffer runs out precisely when it is needed most.

    Underestimating the impact of execution quality at suppliers

    Execution quality is not just product quality; it is the quality of how work is planned, sequenced, controlled, and recorded. In many aerospace plants, especially smaller tier-2s, the formal systems—ERP, scheduling modules, quality databases—tell a clean story. The real system lives in paper travelers, local spreadsheets, and tribal knowledge on the shop floor.

    When execution quality is weak, risk accumulates silently:

    • Work-in-process (WIP) is misaligned with actual constraint resources.
    • Process deviations and concessions are tracked unevenly across cells.
    • Configuration changes are communicated late or implemented inconsistently.
    • Quality issues surface at test or inspection instead of at the point of work.

    On the OEM’s dashboard, on-time delivery (OTD) may look acceptable until these latent issues line up with a surge request, a certification change, or a new non-conformance trend. By the time OTD moves, the underlying execution problem has existed for months or years.

    Examples of how late-stage surprises propagate upstream

    Late visibility on execution failures at suppliers turns local problems into network-wide shocks. Typical patterns include:

    • Hidden yield problems on critical special processes. A tier-2 specializing in complex machining and surface treatments begins seeing higher scrap and rework on a new alloy. Travelers and rework logs are paper-based, so no one notices the trend until the finished-goods buffer drains and multiple late lots converge in inspection. The tier-1 is forced into emergency reprioritization, consuming capacity for other programs.
    • Configuration or drawing effectivity misapplied. A design update changes hole patterns, fastener types, or coatings across multiple part numbers. The supplier updates work instructions for new jobs but misses reactivated legacy orders still in WIP. When assemblies reach integration, mismatches appear, driving rework, concessions, and schedule slips back through the chain.
    • Unseen resource constraints around key people or assets. A small group of qualified special-process operators, or a single certified CMM, becomes the true bottleneck during a ramp. Local supervisors know this, but the OEM sees only aggregate capacity. When demand spikes, lead times stretch in unexpected ways and expedite requests simply move the queue without improving actual throughput.

    In each case, the resilience failure is not lack of contracts or theoretical capacity—it is the absence of shared, timely execution visibility.

    Execution Realities in Tier-1 and Tier-2 Aerospace Suppliers

    Manual scheduling and paper-based control in critical processes

    Even among sophisticated tier-1s, a surprising amount of critical work is still coordinated with manual tools. High-level schedules are generated from ERP or APS, but detailed sequencing often lives on whiteboards, printed dispatch lists, and the experience of a few planners and supervisors.

    Paper travelers remain common for routing, inspection checkpoints, and signoffs. For regulated processes—heat treat, NDT, weld, bond, special coatings—this can technically satisfy compliance but makes it hard to understand real-time status. If a line stoppage occurs due to a furnace outage or failed coupon, the impact on specific customer orders is not obvious without manual triage.

    The result is a fragile link between planning systems and the shop floor. Schedulers can publish a perfect plan at the start of the week, but by mid-week the true sequence diverges as operators adjust to machine issues, missing tooling, or late components. OEMs see the original plan; they do not see the divergence.

    Limited real-time visibility into WIP and quality status

    Most suppliers can answer “Where is my part?”—but not without work. Customer service teams send emails to production, planners walk the floor, supervisors check racks and travelers. The answer is often a snapshot rather than a continuous view.

    Quality status is even harder to see in real time. Non-conformances might be logged in a QMS, but linkage to specific WIP orders and their impact on customer commitments is rarely automatic. An NC that stops a small batch can quietly hold up a critical assembly, while the top-level schedule still assumes the original promise date.

    This opacity forces OEMs to operate on lagging indicators—OTD, aging past-due orders, and concession trends—rather than leading indicators like WIP aging, queue build-up at constraints, or first-pass yield on critical operations.

    Strain from variable OEM demand and expedited requests

    Demand from aircraft and defense programs is rarely smooth. Retrofits, post-certification changes, out-of-sequence work, and campaign-based upgrades mean order books for suppliers can swing significantly month to month. Those swings are often amplified by blanket POs, release patterns, and late-breaking field priorities.

    Without a strong execution layer, suppliers respond with ad hoc expediting: pulling jobs forward, swapping setups, running overtime, and reassigning operators. Each local decision might make sense, but taken together they erode schedule stability. Lead times stretch unpredictably, WIP piles up in the wrong places, and quality risk increases as teams operate in permanent surge mode.

    From the OEM’s perspective, the supplier looks unresponsive or disorganized. From the supplier’s perspective, they are doing everything possible with the tools they have. The missing piece is a shared, data-driven way to prioritize and manage work across customers and programs.

    Signals That Indicate Supplier Fragility

    Chronic expedites and short-notice replanning

    Occasional expedites are normal in complex programs. Chronic expedites are a warning sign. When every critical delivery requires special attention—phone calls, executive escalations, daily status meetings—it indicates that the standard execution system is not robust enough to keep commitments without heroics.

    Similarly, frequent short-notice schedule changes coming from the supplier—”we need to move this out two weeks,” “we can swap these lots,” “we had to hold that batch”—are clues that the internal plan is repeatedly invalidated by issues that should be visible earlier. In stable systems, plans fail gracefully; in fragile ones, they fail suddenly and repeatedly.

    High rates of concessions and escape incidents

    Concessions, use-as-is dispositions, and escape incidents are classic quality signals, but they are also execution signals. A rising concession rate often reflects stressed processes, training gaps, or overloaded inspection capacity. Escapes—non-conformances that reach the OEM or final assembly—usually point to weak integration between quality and execution on the shop floor.

    When concessions become the de facto way to keep schedule, resilience is already compromised. The system is using future risk—potential rework, field findings, or certification scrutiny—to pay for present throughput. That trade rarely works out over the long term.

    Inconsistent or delayed status reporting

    Suppliers that struggle to provide timely, consistent status are typically struggling to see their own system. Weekly spreadsheets compiled by hand, status decks that change format every quarter, and large discrepancies between what is reported and what is observed during on-site visits all suggest weak execution visibility.

    For OEMs, these are not just communication issues; they are early indicators of fragility. If a supplier cannot reliably say where work stands today, it is unlikely they can reliably absorb a design change, ramp, or new compliance requirement tomorrow.

    What Shared Execution Visibility Enables

    Early warning for capacity and quality constraints

    A shared execution layer between OEMs and critical suppliers does not mean exposing every internal detail. It means creating a narrow but accurate window into real production status, WIP, and quality conditions that affect customer commitments.

    With that window, OEMs can see emerging constraints long before they hit OTD: queue growth at a specific special process, extended cycle times on a new configuration, rising NCs tied to a particular tool, work center, or supplier lot. Instead of learning about problems when due dates are missed, OEMs receive early warning signals that enable proactive replanning, alternate sourcing, or engineering support.

    Joint prioritization of orders across programs and customers

    Suppliers often serve multiple OEMs and multiple programs. Without a shared execution view, prioritization becomes a negotiation driven by whoever is loudest or most urgent on a given day. That dynamic increases risk for all parties.

    When OEMs can see, at least in summarized form, how their orders sit in the supplier’s real queue and what constraints are binding, prioritization becomes a joint decision. Programs can align on which units truly protect downstream integration schedules, test campaigns, or field commitments. Suppliers can propose realistic trade-offs grounded in constraint capacity rather than guesses.

    Collaborative root-cause analysis grounded in real data

    Traditional root-cause analysis between OEMs and suppliers is often forensic and slow. Teams reconstruct timelines from travelers, emails, and memory. Data is static and incomplete, and blame dynamics can overshadow learning.

    A shared execution layer changes that dynamic. When both parties can see the same history of WIP movement, machine states, NC events, rework loops, and signoffs, the conversation shifts from speculation to evidence. It becomes easier to distinguish between systemic issues (e.g., under-capacity at a special process, unclear work instructions) and true one-off events. Corrective actions can then focus on changing the execution system, not just closing paperwork.

    Architectures for Multi-Enterprise Execution Layers

    Connecting OEM systems to supplier execution environments

    Most OEMs already exchange data with suppliers through portals, EDI, and PLM integrations: purchase orders, forecasts, drawings, specifications. What is usually missing is a live connection to execution signals on the supplier’s side—order status by operation, WIP location, quality holds, and key timestamps.

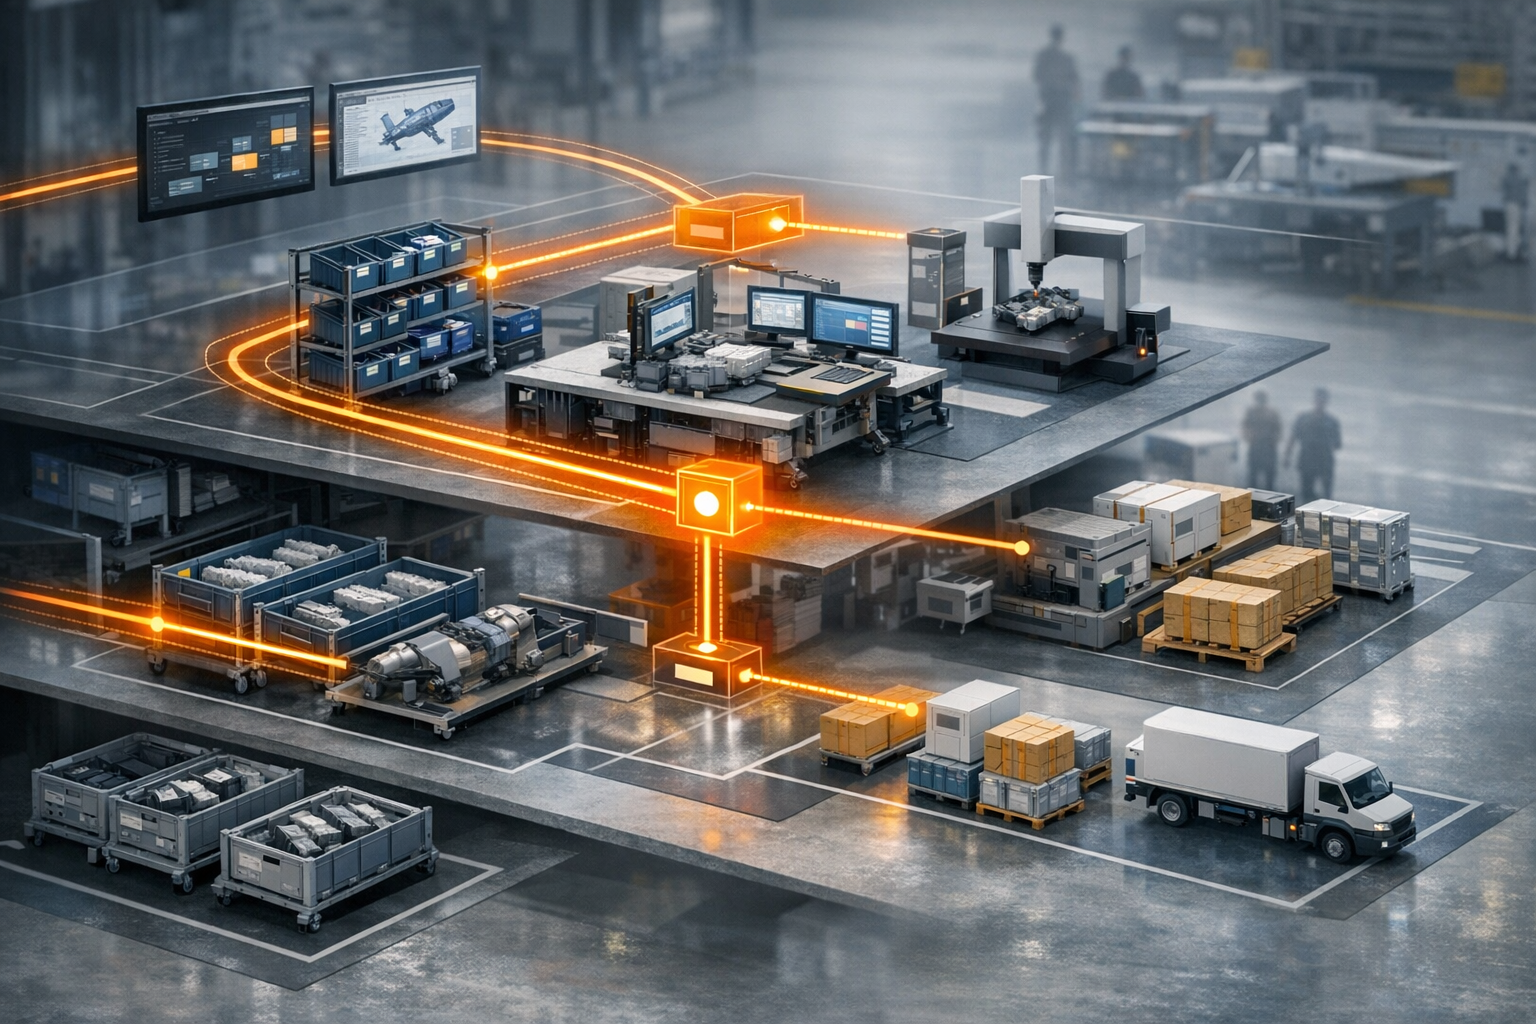
    A multi-enterprise execution layer sits between planning systems (ERP, APS, PLM) and shop-floor reality (MES, travelers, machines). It federates data from supplier environments—whether from existing MES, homegrown systems, or lightweight digital work instructions—and normalizes a small set of status signals that OEMs can consume. Platforms like Connect 981 are designed to operate in this space, without replacing ERP or QMS systems that already exist.

    Data scope and access models that respect IP and export controls

    Aerospace suppliers rightly worry about exposing too much internal data. Intellectual property, commercial terms, and export-controlled technical information all impose real constraints on data-sharing architectures. The goal of a shared execution layer is not to copy entire databases to the OEM, but to expose a minimal set of operational facts necessary for resilience.

    Typical patterns include:

    • Order-level status (e.g., not started / in work / at special process / in inspection / ready to ship).
    • Operation-level milestones and cycle times for agreed critical routes.
    • Aggregated WIP and capacity utilization for key resources, without revealing full routings.
    • Quality event indicators tied to orders (e.g., on quality hold, under engineering review) without disclosing proprietary process details.

    Access can be scoped by program, part family, or contract, and strictly limited to what is needed to manage risk. Export-controlled data remains governed by existing regulatory frameworks and technical safeguards; the execution layer should be designed to operate within those constraints, not bypass them.

    Standardizing core status and traceability signals

    Every supplier has its own internal codes, routing structures, and naming conventions. For OEMs trying to manage hundreds or thousands of suppliers, consuming this diversity directly is impossible. A practical multi-enterprise execution layer therefore relies on standardizing a small vocabulary of status and traceability signals.

    Examples include:

    • Common order lifecycle states (planned, released, in process, at external process, in final inspection, ready to ship, shipped).
    • Key timestamps (release, start, finish by work center family, quality release).
    • Serialized or lot-based identifiers that support downstream traceability.
    • High-level quality flags (NC present, concession requested, deviation approved).

    Internally, suppliers can continue to operate with detailed MES or paper systems. The execution layer acts as a translator, projecting just enough structured information outward to support network-level visibility without forcing every plant to adopt identical tools.

    Resilience Metrics Beyond On-Time Delivery

    Variability in lead time and schedule adherence

    On-time delivery is a lagging, binary signal. Two suppliers with 95% OTD can behave very differently under stress. One may have tight lead-time distributions and stable adherence to start dates; the other may achieve OTD through constant firefighting and large swings in actual cycle times.

    Execution-aware resilience metrics focus on variability as much as averages. Key views include distribution of actual lead times vs. planned, adherence to operation start/finish windows, and sensitivity of those metrics to demand changes. High variability is a direct indicator of fragility, even when OTD is still formally acceptable.

    Quality stability and reoccurrence of issues

    Quality metrics like defect rates and DPPM are standard, but resilience requires looking at how issues behave over time. Are similar NCs recurring across lots and configurations? Do corrective actions lead to stable improvements, or do problems resurface after a short period?

    With execution-layer data, OEMs and suppliers can track NC rates by operation, shift, and configuration, and correlate them with process conditions (e.g., machine, tooling set, supplier lot). Persistent or migrating patterns signal where the system is absorbing risk rather than eliminating it. A resilient network shows decreasing recurrence and faster convergence of corrective actions.

    Recovery performance after disruptions

    No aerospace network can avoid disruptions: machine failures, late material, regulatory changes, or field-driven engineering orders will always occur. Resilience is therefore measured at least as much by recovery performance as by baseline performance.

    Execution-aware metrics include time-to-detect issues, time-to-contain (e.g., isolate affected WIP and inventory), and time-to-recover committed schedules. These are difficult to measure with traditional reporting but become natural outputs of a connected execution environment where events and response actions are captured in context.

    Practical Steps Toward a More Resilient Aerospace Network

    Prioritizing critical suppliers and parts for deeper integration

    Building a shared execution layer across an entire supply base is a multi-year journey. The starting point is to prioritize. OEMs should identify a small set of suppliers and part families where execution risk is most consequential: long-lead structural components, critical systems, single-source special processes, or assemblies that frequently drive line stoppages.

    For those suppliers, the goal is to move beyond quarterly business reviews and spreadsheet-based tracking toward a more direct connection to their execution environment. That may begin with simple, structured status feeds and progress over time to richer WIP, constraint, and quality visibility as trust and capability grow.

    Pilots using platforms like Connect 981 for shared visibility

    Early pilots should be scoped narrowly but designed to exercise the full concept of connected execution. A typical pattern is to select one program, one or two suppliers, and a handful of part families, then instrument the full order flow from OEM release through supplier execution to final delivery using a shared platform such as Connect981.

    The pilot’s purpose is not to implement every feature but to learn how real execution data changes decision-making: how earlier detection of WIP bottlenecks affects replanning, how transparent queues influence expedite behavior, and how embedded traceability simplifies audits and concessions. These insights then guide broader rollout.

    Embedding execution expectations into new contracts and SOWs

    Finally, resilience must be designed into commercial and technical relationships, not added as an afterthought. As OEMs renew contracts and statements of work, they can explicitly define expectations for execution visibility and data-sharing, alongside traditional quality and delivery requirements.

    Examples include requirements for order-level status updates through designated digital channels, participation in defined multi-enterprise execution platforms, timely capture of traceability data at critical operations, and support for joint root-cause investigations using shared data. The goal is not to impose a single system everywhere, but to make connected execution a standard part of what it means to be a strategic aerospace supplier.

    In a regulated, high-consequence industry, resilience cannot be purchased solely through second sources and inventory. It has to be built into how work is executed and seen across organizations. By investing in a shared execution layer—where OEMs and suppliers operate from the same real-time understanding of production, constraints, and quality—networks become less reactive, less fragile, and better prepared for the next wave of program and regulatory pressures.

  • Closing the Engineering Change–Execution Gap in Aerospace Manufacturing

    Closing the Engineering Change–Execution Gap in Aerospace Manufacturing

    In aerospace, engineering change is supposed to be the most controlled process in the company. Every engineering change notice (ECN) passes through reviews, signatures, and workflow steps inside PLM or equivalent systems. On paper, the digital thread looks clean.

    But the real test of engineering change management is not whether an ECN was approved. It is whether the right hardware, at the right point in the build, at the right supplier, actually changed when and how it should.

    For teams putting this topic into daily operation, execution systems for aerospace manufacturing, shop floor execution control, a connected execution platform help connect the concept to traceability, work-order reality, and audit-ready evidence.

    This is where the gap appears between formal engineering change control and real execution. The headline metrics we track in aerospace programs rarely show how well changes are absorbed by production systems. The difference between a stable program and a fragile one often comes down to how repeatably you can push change through a live, regulated manufacturing environment without losing control of configuration.

    The Nature of Engineering Change in Aerospace Programs

    Aerospace hardware lives for decades. That longevity, combined with safety and regulatory expectations, makes engineering change both unavoidable and unusually high-stakes.

    Drivers: safety, performance, cost, and obsolescence

    Most significant aerospace engineering changes fall into one of a few categories:

    • Safety and reliability: design corrections, fatigue findings, durability improvements, or corrective actions from incidents and test results.
    • Performance and capability: weight reduction, fuel efficiency improvements, avionic upgrades, new mission variants, or customer-specific options.
    • Cost and manufacturability: design for manufacturability and assembly (DFMA) updates, alternative processes, part consolidation, and yield-driven tweaks.
    • Obsolescence and supply risk: discontinued components, changing export controls, or supplier exits that force redesign or alternate sourcing.

    In all these cases, engineering change is not just a design activity. It is an operational event that must propagate through production systems, test, maintenance, and the supply chain while maintaining certification and traceability.

    The volume and cadence of ECNs over long program lives

    On a new or evolving platform, hundreds or thousands of ECNs can occur over the life of a program. Early years often see a heavy flow of changes as flight test findings, producibility feedback, and customer changes accumulate. Even mature programs see ongoing churn from obsolescence, regulatory updates, and incremental improvements.

    This cadence matters because it reveals why one-off, manually coordinated change handling is fragile. If each ECN triggers ad-hoc email campaigns, spreadsheet impact logs, and one-time special instructions, the system will eventually miss something. The operational question is not can we execute this change? but can we execute change reliably, repeatedly, and predictably under load?

    Implications for certified and flight-critical hardware

    For flight-critical systems and safety-related components, the stakes are even higher. Configuration control is directly connected to airworthiness and regulatory approval. When a change affects:

    • Primary structure,
    • Flight controls, avionics, or propulsion interfaces, or
    • Escape, fire protection, or other safety systems,

    any misalignment between design intent and as-built configuration is not just a cost or schedule issue. It is a potential safety and certification issue.

    This is why regulators and customers expect clean, auditable evidence that the right change was applied to the right hardware at the right time – not just a signed ECN in PLM.

    Where Change Management Collides with Execution

    Most aerospace organizations have mature engineering change workflows. The collision happens when those workflows meet real WIP, real schedules, and real suppliers.

    ECNs approved in PLM but not reflected in work instructions

    In many factories, engineering lives primarily in PLM and CAD, while execution lives in a combination of ERP, MES, work travelers, and local work instructions. When PLM issues an ECN, the translation into executable work is often partially manual:

    • Manufacturing engineering updates routings and bills of material in ERP.
    • Planners or industrial engineers update operation-level instructions in MES or document management systems.
    • Supervisors communicate “use this new drawing” or “follow this deviation” on the floor.

    Any latency or inconsistency in that translation creates a window where work can be started or completed using the wrong version of data. The PLM record says the change is effective; the actual instructions in front of the operator say something else.

    WIP caught between old and new configurations

    The hardest part of engineering change is rarely the future builds; it is the in-process work. Typical questions when a change lands:

    • Which units can ship as-is under the previous configuration?
    • Which assemblies must be reworked, and how invasive is that rework?
    • Where is each serial number physically and process-wise in the build?
    • Do we apply the change by effectivity date, shipset, or serial number range?

    Without a system that can answer these questions in real time, teams often fall back to manual reconciliation of WIP travelers, spreadsheets, and tribal knowledge. That slows decisions and increases the probability that something slips through – a unit reworked unnecessarily, or worse, a unit that should have been reworked but was missed.

    Suppliers building to outdated requirements

    The same misalignment appears across the supply chain. Tiered aerospace supply chains frequently operate on:

    • Released drawings and specs sent via portals or email,
    • Purchase order references to configuration or revision, and
    • Periodic pushes of updated documents, sometimes without clear effectivity rules.

    If suppliers do not have a clear, system-backed view of which revision applies to which orders and serials – and if the OEM or integrator cannot see what configuration is actually being built – ECNs become a source of chronic confusion. It is common to discover parts in transit or in incoming inspection that are perfectly built to an old but no-longer-acceptable configuration.

    Configuration Control Requirements in Regulated Environments

    These operational collisions are not just internal headaches; they sit directly under aerospace quality and regulatory expectations.

    AS9100 expectations for configuration management

    AS9100 establishes clear expectations around configuration management, including identification and traceability, change control, and status accounting. In practice this means you must be able to show:

    • How configurations are defined and baselined,
    • How changes are reviewed, approved, and released, and
    • How those changes are applied to specific hardware, with records to prove it.

    Critically, configuration management in AS9100 is not only a design office concern. It extends into manufacturing, inspection, test, and supplier management. An ECN that cannot be traced cleanly into WIP, serial numbers, and supplier lots is a configuration risk, even if the PLM process is immaculate.

    FAA/EASA implications when changes affect flight safety

    When design changes touch aspects of the aircraft or system that are safety-significant, configuration evidence becomes part of the overall airworthiness case. Regulators expect that:

    • The affected hardware is fully understood and controlled during transition.
    • Test and conformity articles are clearly identified with their configuration state.
    • Fielded equipment configuration can be traced back to approved design baselines.

    Gaps between ECN intent and actual as-built configuration can ripple into service bulletins, retrofit campaigns, or in extreme cases, grounding and rework of in-service fleets. The cost and schedule impact of a configuration escape often dwarfs the cost of implementing the change correctly the first time.

    Customer-specific configuration control practices

    Defense and space customers often add another layer of configuration control expectations: contract-specific baselines, government-approved configuration items, and formal change boards with customer participation. For high-value flight hardware and classified programs, the ability to prove that a given serial number conforms exactly to the authorized configuration is non-negotiable.

    This environment amplifies the need for an execution layer that can connect contract, configuration baseline, ECN, and as-built evidence without relying on manual reconstruction during audits or investigations.

    The Role of the Execution Layer in Change Management

    Bridging the gap between PLM-managed change and real production behavior requires a layer that understands where every unit is, what configuration it is supposed to be, and which instructions and materials are being applied at each step. That is the execution layer.

    Identifying affected WIP, lots, and serial numbers in real time

    When an ECN is approved, the first operational question is impact: which work, in which state, needs attention? An execution layer can answer this by holding:

    • Serial-level or lot-level tracking of units and subassemblies,
    • Their current operation or station, and
    • The specific revision of instructions, BOMs, and specs applied at each step.

    With that data, impact analysis shifts from a manual hunt to a query: “Show all hardware where operation X is complete under revision A, but ECN-123 requires revision B by shipset.” This is the difference between reacting slowly with spreadsheets and responding quickly with confidence.

    Coordinating hold, rework, and scrap decisions

    Once affected hardware is identified, teams must decide what to do with it. Some units can continue under old configuration, some must be held pending engineering disposition, others require specific rework, and in rare cases scrap is unavoidable.

    An execution layer supports this by allowing coordinated actions against actual WIP:

    • Placing holds at entity, lot, or operation level based on ECN impact.
    • Attaching rework plans and deviations directly to affected serials.
    • Capturing disposition decisions and their rationale for future traceability.

    This is materially different from issuing a general “stop work” email and hoping local teams interpret it consistently.

    Updating instructions and capturing evidence of correct configuration

    Change only becomes real on the shop floor when the work instructions and checks in front of the operator reflect the new intent. An effective execution layer can:

    • Link ECNs to specific operations, inspection steps, and data collections.
    • Push revised instructions and control plans to the point of work with clear effectivity.
    • Capture digital evidence (measurements, signoffs, test results) that the new configuration was built as intended.

    The result is not just that change is executed; it is provably executed, with configuration evidence embedded in the production record, not reconstructed later.

    Synchronizing PLM, ERP, and Shop Floor During Change

    Most aerospace manufacturers rely on three primary system families: PLM for design and change, ERP for planning and commercial transactions, and various MES/quality systems for execution. During engineering change, these boundaries become pressure points.

    Translating engineering changes into executable work

    PLM is excellent at managing design data and formal change workflows, but ECNs must be translated into:

    • Updated part numbers, revisions, and alternates in ERP,
    • Changed routings and work centers, and
    • New or modified work instructions and inspection plans.

    If these translations are handled via disconnected uploads, PDFs, and manual data entry, it is almost guaranteed that change will hit the shop floor inconsistently. A connected execution layer can consume structured change data from PLM and drive updates into routings, instructions, and checks in a controlled, effectivity-aware way.

    Managing effectivity dates and serial-level applicability

    Effectivity is where theory and reality part ways. On paper, changes might reference:

    • Calendar effectivity (after a certain date),
    • Lot or batch numbers, or
    • Serial number ranges and block points.

    On the floor, this only works if the system executing work knows which unit is which, and which rule applies. An execution layer can act as the arbiter of effectivity, combining:

    • PLM-declared effectivity logic,
    • ERP order and delivery requirements, and
    • Real-time WIP status and serial genealogy.

    Without that, organizations fall back to blanket cutovers: “Everything started after this date uses the new design,” which often fails when long-travelers, rework, or out-of-sequence work are in play.

    Ensuring suppliers receive and acknowledge updated requirements

    Supplier synchronization is often the weakest link. Change packages might be pushed through portals, but acknowledgement and adoption are managed by email threads and status meetings. A more robust pattern is to treat suppliers as extensions of the execution layer:

    • Expose current configuration requirements against specific orders and serials.
    • Track which suppliers have accepted and implemented new revisions.
    • Tie incoming inspection plans to expected configuration, with fast feedback when mismatches appear.

    This does not require every supplier to run the same internal systems, but it does require a shared picture of configuration state that goes beyond static drawings.

    Case-Style Scenarios of Better and Worse Change Handling

    Abstract principles become clear when viewed through scenarios. The following examples are anonymized composites drawn from typical aerospace environments.

    A change applied cleanly with full execution visibility

    An integrator discovers a fatigue concern in a structural bracket. Engineering issues an ECN that changes material and adds an extra inspection step. The execution layer maps the ECN to affected assemblies and identifies:

    • All WIP shipsets where the bracket has been installed under the old configuration.
    • All upcoming work orders where the old bracket is planned but not yet installed.
    • Supplier lots of the old bracket still in transit or stock.

    Operations immediately places targeted holds on affected WIP, issues rework instructions to remove and replace brackets where necessary, and updates work instructions so future builds automatically route through the new inspection. Suppliers receive updated requirements tied to specific open orders. Within days, the organization can produce a clear list of serial numbers with old vs new configuration and the rework status of each.

    A change misapplied due to missing WIP and supplier status data

    In a different program, a similar bracket change is approved in PLM and cascaded via revised drawings. The ERP team updates part numbers, and a generic notice goes out to the shop and key suppliers. There is no shared system showing where brackets are installed or which supplier lots are in which assemblies.

    Weeks later, incoming inspection identifies a mix of old and new brackets still arriving. A field issue triggers a deeper review, revealing that multiple aircraft left final assembly with the old bracket in positions that were supposed to be reworked. The team spends months reconstructing configuration from paper travelers, warehouse logs, and emails to determine which units must be inspected or modified in service.

    The core failure is not engineering intent – it is the absence of an execution layer that could tie ECN, WIP, and supplier status together in real time.

    Lessons learned for future change events

    Across these scenarios, the same lessons emerge:

    • Change velocity exposes execution maturity: processes that appear adequate under low change volume break down under real program pressure.
    • WIP visibility is non-negotiable: you cannot control what you cannot see at the level of serials, lots, and operations.
    • Suppliers are part of the configuration system: without integrated visibility into supplier adoption of change, your configuration story is incomplete.
    • Evidence must be built-in: traceability that depends on reconstruction after the fact is fragile and expensive.

    Designing a Repeatable Change-Execution Playbook

    Closing the engineering change–execution gap is less about heroics and more about building a repeatable playbook, supported by the right execution infrastructure.

    Standardizing impact analysis steps using execution data

    A robust playbook starts with a consistent impact analysis pattern, driven by data rather than ad-hoc judgment. For each ECN, the organization should be able to answer quickly:

    • Which part numbers, assemblies, and operations are affected?
    • Which WIP units, by serial and location, intersect with those operations under the old configuration?
    • Which inventory lots and supplier orders are tied to the old vs new design?

    With an execution layer in place, these questions become queries and dashboards rather than war rooms and email chains.

    Defining roles and responsibilities across engineering, quality, and operations

    Process alone is not enough; roles must be clear. A typical pattern for aerospace change execution:

    • Engineering owns design intent, ECN content, and effectivity rules.
    • Manufacturing engineering/operations own translation into routings, instructions, and physical work changes.
    • Quality owns risk assessment, additional controls, and verification that as-built configuration matches intent.
    • Supply chain owns propagation and confirmation of change across external suppliers.

    An execution layer gives each group a shared, live view of the same hardware and the same change event. That shared context is what turns roles into a coherent process rather than parallel activities.

    How platforms like Connect 981 can support change orchestration

    An aerospace-focused execution platform such as Connect 981 is designed to sit between planning systems and the real world of WIP, test, and suppliers. In the context of engineering change, that means:

    • Ingesting structured ECN and configuration data from PLM.
    • Maintaining serial-level and lot-level genealogy across operations and suppliers.
    • Enforcing effectivity-aware work instructions and inspection plans at the point of work.
    • Providing real-time visibility of impact, holds, and rework across the production system.

    This does not replace PLM or ERP; it complements them by handling what they are not built to do: orchestrate change in a live, regulated execution environment. In the same way that headline program metrics hide the real execution system underneath, traditional engineering change metrics hide how hard it is to actually make change stick. The organizations that invest in a true execution layer are the ones that will be able to change fast without losing control of configuration.

  • Designing a Digital Manufacturing Architecture for Aerospace Execution

    Designing a Digital Manufacturing Architecture for Aerospace Execution

    Designing a Digital Manufacturing Architecture for Aerospace Execution

    Aerospace manufacturers are under pressure to deliver more, faster, with tighter compliance and deeper traceability. Many already have PLM, ERP, MES, and quality systems in place, yet still struggle to answer basic questions in real time: What is actually happening on this program today? Where are we off-plan, and why? Which risks are accumulating in the supply chain right now? That gap between planning numbers and operational reality is the same visibility problem described in the execution-centric view argued in the scoreboard article—but now at the level of factory systems.

    This article proposes a practical, technology-agnostic digital manufacturing architecture tailored to aerospace. It focuses on clear system roles, data boundaries, and integration flows, with a specific emphasis on introducing an execution layer that sits between planning systems and the real world of production. The goal is not a greenfield redesign, but a roadmap that works in brownfield, multi-site, and multi-supplier environments.

    For teams putting this topic into daily operation, Connect 981’s aerospace execution solutions help connect the concept to traceability, work-order reality, and audit-ready evidence.

    For teams putting this topic into daily operation, part genealogy and traceability, part traceability and as-built evidence help connect the concept to traceability, work-order reality, and audit-ready evidence.

    The same operating model also depends on shop floor execution control, a connected execution platform, Connect 981’s aerospace operations guidance, practical aerospace operations FAQs, especially when decisions have to move across quality, production, suppliers, and program leadership without losing context.

    The Current State of Digital Manufacturing in Aerospace

    Typical system inventories at OEMs and larger suppliers

    Most aerospace OEMs and tiered suppliers already operate a dense landscape of systems. A typical inventory includes:

    • PLM and PDM for engineering data, configurations, changes, and controlled technical documentation.
    • ERP for demand, MRP, capacity planning, purchasing, inventory, and financials.
    • MES or shop-floor systems for work dispatching, data collection, and sometimes machine integration.
    • Quality systems (QMS, eQMS, NCR/FRACAS tools) for inspections, non-conformances, concessions, corrective actions, and approvals.
    • Point solutions for tooling, calibration, maintenance, document control, and test systems.

    Each of these systems solves a real problem, often very well. The challenge is that they rarely form a coherent operational picture. Program leaders, industrialization engineers, and production managers end up assembling their own view through spreadsheets, status meetings, and ad hoc dashboards.

    Pockets of automation alongside manual islands

    A common pattern is deep automation in small pockets (for example, a highly automated machining cell or test facility) surrounded by manual coordination. Operators may log data digitally, but routing changes, rework decisions, and schedule recovery plans often move via email, shared drives, or side conversations.

    This creates islands where data exists, but is not connected. A machine may be perfectly integrated to an MES, yet program management has no live visibility into whether today’s critical serial numbers are on track, blocked by quality, or waiting on supplier hardware.

    Integration gaps that directly impact execution clarity

    From an execution standpoint, the most damaging gaps are usually not missing systems, but missing contextual integration. Examples include:

    • PLM sends BOMs and routings to ERP, but late engineering changes are not reliably propagated to the work instructions on the floor.
    • MES collects operation completions, but ERP still shows the plan until someone manually reconciles exceptions.
    • Quality holds and concessions live in a separate system, so planners cannot see which orders are blocked in real time.
    • Supplier status is maintained in portals or emails, not as structured, machine-readable signals tied to specific assemblies and serial numbers.

    The result is a fragmented view of reality. KPI dashboards may look healthy, while the true execution system is fighting fires. Closing this gap requires treating the execution layer as a first-class architectural component.

    Core System Roles in Aerospace Manufacturing

    PLM as design and configuration authority

    In regulated aerospace, PLM is the design authority. It owns product definitions, configurations, CAD, controlled documents, and engineering change processes. PLM defines what is allowed to be built and under which configuration rules.

    For a digital thread to function, PLM must clearly expose authoritative structures: engineering BOMs, manufacturing BOMs, routings, and approved work instructions. Downstream systems should not be re-creating these structures independently; they should consume them via controlled interfaces with explicit versioning, effectivity, and change control.

    ERP as planning and financial backbone

    ERP is the planning and financial backbone. It translates product definitions into demand, supply, capacity, and cost. It drives MRP, purchasing, lead times, and production orders. However, ERP fundamentally operates on planned states and summarized events.

    In aerospace, this distinction is crucial. ERP knows what should have happened: which work orders should be in which status and when. It is not designed to track every micro-state, rework loop, or configuration-specific deviation at the level required for certification and root-cause analysis.

    MES and plant systems for local control and data collection

    MES and plant systems typically orchestrate work within a facility: dispatching operations, collecting inspection results, interfacing with equipment, and enforcing some aspects of process control. In many aerospace plants, legacy MES implementations are tightly coupled to specific lines or technologies, and their data models mirror local needs rather than program-wide visibility.

    A well-implemented MES is vital, but it is still plant-centric. It usually lacks a program- and configuration-centric view that spans multiple sites and external suppliers. This is where an explicit execution layer becomes necessary.

    Quality systems for inspections, NCs, and approvals

    Quality systems are the backbone of compliance: they capture non-conformances, concessions, corrective actions, inspection plans, and audit evidence. In AS9100 and similar environments, they must remain authoritative for these records.

    The architectural challenge is that quality events are often logged after the fact or in systems disconnected from live production status. That makes it hard to see, in real time, which serial numbers or assemblies are blocked, under concession, or carrying elevated risk. The execution layer has to surface quality status as part of the operational picture without compromising the QMS as the system of record.

    Introducing the Execution Layer as a First-Class Component

    Why existing systems struggle to represent live operational context

    Most aerospace organizations discover that even with mature PLM, ERP, MES, and QMS, they still cannot reliably answer questions like:

    • For this program, which serial numbers are currently in process, where are they physically, and who is working on them?
    • Which operations are blocked by missing parts, tooling issues, or quality holds, and what is the downstream schedule impact?
    • How many deviations from standard work have occurred this week, and how are they distributed across suppliers and sites?

    The reason is architectural: each system holds a piece of the puzzle, but none is responsible for assembling current execution context across the entire value stream. That is the job of an explicit execution layer.

    Execution layer responsibilities distinct from MES and ERP

    A dedicated execution layer should not try to become another MES or another ERP. Its distinct responsibilities typically include:

    • Live orchestration and status: maintaining a single, near-real-time model of every order, operation, and serial number across plants and key suppliers.
    • Contextualizing data: joining work orders, configurations, quality events, and supplier signals into a coherent timeline per unit or lot.
    • Exception management: making deviations from plan (delays, rework, holds, missing material) visible quickly and in the right context.
    • Embedded traceability: capturing genealogy and process evidence as work happens, rather than reconstructing it later.

    In other words, the execution layer is the operational nervous system that connects planning intent to what is actually happening, minute by minute.

    Supporting multi-site and multi-supplier coordination

    Aerospace programs are almost always multi-site and multi-supplier. An execution layer must therefore be designed for federated visibility from the outset. That means:

    • Normalizing key identifiers (part numbers, serials, lots, orders) across organizations.
    • Defining data contracts with suppliers that expose status, quality events, and certification documents in structured form.
    • Handling different levels of system maturity—some suppliers may have MES, others may only have spreadsheets.

    Platforms like Connect 981 operate in this space: not by replacing existing systems of record, but by serving as the execution fabric that links them into a coherent operational picture.

    Key Data Flows in a Connected Aerospace Architecture

    From PLM to execution: configurations, BOMs, and work instructions

    The first critical flow is from PLM to the execution layer. Key elements include:

    • Configuration structures (engineering and manufacturing BOMs) with clear versioning and effectivity.
    • Process definitions: routings, operation sequences, key characteristics, and inspection plans.
    • Controlled work instructions and reference documents that must be available at the point of work.

    The execution layer does not re-author this data; it consumes it as authoritative, then maps it to specific orders, serial numbers, and sites. When engineering changes occur, the execution layer should be able to show exactly which in-process units are impacted and where rework or special instructions are required.

    From execution to ERP: completions, variances, and schedule impact

    The second major flow runs from the execution layer back to ERP. ERP needs summarized events: operation starts and completions, scrap, yield, and sometimes high-level reasons for variance. The execution layer should:

    • Capture detailed execution events and statuses in its own model.
    • Translate those events into the coarser transactions ERP expects.
    • Push schedule-relevant status updates early enough that planners can adjust, rather than learning about delays after the fact.

    This preserves ERP’s role as the planning backbone while ensuring its view of progress reflects what is actually happening on the floor and across suppliers.

    From quality systems to execution: holds, concessions, and approvals

    Quality systems remain the system of record for non-conformances, concessions, and approvals. However, the execution layer must be aware of their impact on work. Architecturally, this usually means:

    • Quality events are created and managed in the QMS.
    • The execution layer subscribes to these events via an integration, enriched with identifiers such as serial numbers, work orders, and affected operations.
    • The execution layer enforces the operational consequences: holds, rework routing, special inspections, or additional approvals.

    This separation preserves auditability while ensuring that quality decisions have an immediate and visible impact on execution.

    From suppliers to OEMs: status, genealogy, and certification data

    Supply chain visibility is often the weakest part of aerospace architectures. A mature execution layer should support:

    • Status updates for critical parts and assemblies tied to specific orders and serials.
    • Genealogy data at the level of lot, batch, and key serialized components.
    • Certification artifacts (CoCs, test reports, inspection records) attached to the right units in a machine-readable way.

    For suppliers with limited digital capabilities, this may start as structured data submissions via controlled templates or lightweight portals. Over time, deeper system-to-system integrations can be introduced, but the architecture should not assume all sites start at the same maturity level.

    Governance, Ownership, and Change Control

    Defining system-of-record responsibilities

    One of the most important architectural decisions is clarifying system-of-record boundaries. A practical pattern for aerospace is:

    • PLM is the system of record for product definition, configurations, and controlled engineering documents.
    • ERP is the system of record for demand, orders, inventory, and financial transactions.
    • QMS is the system of record for quality events, approvals, and audit trails.
    • Execution layer is the system of record for current operational state: where each unit is, what has been done, and which exceptions are active.

    Being explicit about these roles avoids duplication and helps resolve disputes when data disagree across systems.

    Managing master data across organizational boundaries

    Aerospace architectures often fail not because of interfaces, but because of inconsistent master data. Practical steps include:

    • Adopting clear, shared identifiers for parts, configurations, serials, and orders.
    • Defining who owns which reference data (e.g., part families, operation codes, defect codes) and how changes propagate.
    • Ensuring that suppliers receive and return identifiers that can be reconciled across systems.

    The execution layer can help here by acting as the place where inconsistent identifiers are mapped and reconciled, but it cannot fix master data without a governance process.

    Handling upgrades and new capabilities without disrupting operations

    Given the long life of aerospace programs, architectures must tolerate system upgrades and replacements. An interface-first, execution-centered design helps by:

    • Decoupling core execution logic from any single MES or ERP implementation.
    • Using stable APIs and data contracts at the execution layer boundary.
    • Allowing local systems to evolve, as long as they continue to honor those contracts.

    This approach reduces the risk that a plant-level MES replacement or ERP upgrade will destabilize program-level visibility.

    Building the Architecture Incrementally

    Starting with critical programs or product families

    Attempting to re-architect the entire enterprise at once is rarely feasible. A more workable approach is to start with one critical program or product family where visibility gaps are already painful. For that scope, define:

    • The minimum set of systems that must participate (PLM, ERP, QMS, key suppliers, key plants).
    • The execution questions that must be answerable in real time (e.g., status by serial number, critical path operations, open concessions).
    • The data flows required to answer those questions reliably.

    Once the execution model for that program is stable, you can extend patterns and integrations to adjacent programs and suppliers.

    Interface-first approaches to connecting legacy systems

    Brownfield aerospace environments contain many legacy systems that cannot be easily replaced. An interface-first strategy acknowledges this reality:

    • Identify where each system already emits useful data (reports, exports, log files, APIs) and how often.
    • Wrap those outputs in adapters that normalize them to the execution layer’s data model.
    • Prioritize bidirectional interfaces where immediate feedback is valuable (e.g., quality holds that must stop work).

    This allows the execution layer to emerge without requiring big-bang system changes. Over time, some legacy components can be simplified or retired as their roles are subsumed into better-aligned platforms.

    Patterns for introducing platforms like Connect 981

    When introducing an execution platform such as Connect 981, the risk is often organizational rather than technical. Productive patterns include:

    • Framing it as the execution fabric, not another system of record that competes with PLM or ERP.
    • Aligning with compliance needs: using early pilots to prove that embedded traceability and live status reduce audit effort.
    • Anchoring pilots in measurable problems: schedule adherence on a key program, reduced time-to-detect for escapes, or compressed response time to supplier disruptions.

    The goal is to build confidence that the execution layer improves control without forcing disruptive rip-and-replace strategies.

    Measuring Success of a Digital Manufacturing Architecture

    Execution-oriented metrics: visibility, traceability, and response time

    Success for this architecture should be measured in execution outcomes, not just IT milestones. Useful metrics include:

    • Time required to determine the exact status of any unit or lot on a program.
    • Coverage and completeness of digital traceability, including suppliers.
    • Average time from issue detection (quality, material, process) to containment and plan adjustment.

    These metrics directly reflect whether the execution layer is closing the gap between plan and reality.

    Compliance and audit outcomes

    In regulated aerospace environments, architecture should also be judged by compliance friction. Indicators include:

    • Reduction in manual effort to assemble evidence for audits.
    • Fewer late discoveries of missing records or incomplete traceability.
    • Ability to answer auditor questions by navigating live data rather than reconstructing history.

    When the execution layer is working, audit readiness becomes a byproduct of normal operations instead of a periodic crisis.

    Supplier and site adoption indicators

    Finally, a digital manufacturing architecture only delivers its full value when suppliers and sites adopt it. Leading indicators include:

    • Percentage of critical suppliers providing structured status and genealogy data through defined interfaces.
    • Sites using the execution layer as their primary view of work status, rather than private spreadsheets.
    • Cross-functional teams (engineering, quality, supply chain) referencing a shared execution view in decision-making.

    These behaviors show that the architecture has moved beyond an IT project and become an operational asset.

    From Fragmented Systems to a Connected Execution Architecture

    Aerospace performance is increasingly determined not by isolated system capabilities, but by how well those systems are connected into a coherent execution picture. PLM, ERP, MES, and QMS each have essential roles, yet none by itself can provide the operational clarity and embedded traceability that modern programs demand. That requires an explicit execution layer—an architecture that treats real-time context, exceptions, and genealogy as primary objects.

    By advancing toward this architecture incrementally—program by program, supplier by supplier—organizations can move from the misleading comfort of high-level scoreboards to a grounded understanding of how their production systems actually behave. That shift, more than any single technology, is what will differentiate stable aerospace manufacturers from those constantly surprised by their own systems.

  • Beyond the Scoreboard: Execution Systems for Aerospace Manufacturing Knowledge Hub

    Beyond the Scoreboard: Execution Systems for Aerospace Manufacturing Knowledge Hub

    Cluster map

    Links will become clickable once the target pages are published.

    • {{rsc:link|ref=post_id:5872|text=The Aerospace Scoreboard Is Lying to You|fallback=keep_text}}

    Revenue, deliveries, backlog, market cap. These are the numbers that dominate aerospace headlines and board slides. They look like a scoreboard. One OEM up, another down. A simple narrative of winners and losers.

    For teams putting this topic into daily operation, Connect 981’s aerospace execution solutions help connect the concept to traceability, work-order reality, and audit-ready evidence.

    For teams putting this topic into daily operation, execution systems for aerospace manufacturing, shop floor execution control help connect the concept to traceability, work-order reality, and audit-ready evidence.

    The same operating model also depends on a connected execution platform, Connect 981’s aerospace operations guidance, practical aerospace operations FAQs, closing the Engineering Change Execution Gap, especially when decisions have to move across quality, production, suppliers, and program leadership without losing context.

    But aerospace is not a sales competition. It is a tightly constrained execution system that stretches across OEMs, tiered suppliers, engineering teams, regulators, and operators – over timelines measured in years or decades.

    This knowledge hub explains why traditional KPIs are increasingly disconnected from operational reality, and what actually determines performance in modern aerospace manufacturing: execution systems, digital manufacturing platforms, and the connected operational layer between planning and the physical world.

    It is built for aerospace manufacturers, suppliers, engineering leaders, operations teams, and buyers evaluating manufacturing technology. It anchors the perspective introduced in The Aerospace Scoreboard Is Lying to You and extends it into a structured view of systems, processes, and architectures that define execution maturity in aerospace.

    What “Execution Systems” Mean in Aerospace Manufacturing

    In aerospace, an execution system is not a single software product. It is the combined set of people, processes, and digital platforms that connect engineering intent to compliant, physical output at the factory and across the supply chain.

    Practically, this execution layer sits between planning and reality:

    • Above: Enterprise planning and design – ERP, PLM, MRP, financial systems, program management tools.
    • Below: The physical world – machining, special processes, assembly, inspection, test, and delivery.

    The execution layer is where work is actually released, controlled, measured, and verified. It includes:

    • Manufacturing Execution Systems (MES) for work order control, routing, data collection, and enforcement of process steps.
    • Industrial IoT (IIoT) connections for capturing real-time signals from machines, tools, inspection stations, and test rigs.
    • Quality and compliance workflows embedded into the point of work, not bolted on after the fact.
    • Digital thread and traceability linking requirements, design changes, nonconformances, and as-built records to each serialized part and assembly.
    • Supplier collaboration platforms that extend this control and visibility across the aerospace supply chain.

    In a mature aerospace environment, this execution layer becomes the operational source of truth. It is where you see what is actually happening – not what the plan assumed would happen.

    Why Execution Systems Matter Operationally in Aerospace

    Aerospace manufacturing operates under unique constraints:

    • Long certification cycles and strict regulatory oversight.
    • Deep, globally distributed supply chains with critical single-source dependencies.
    • Complex configurations and variant management over decades of program life.
    • High consequence of quality escapes and safety-related failures.

    In this context, scoreboard metrics like deliveries and revenue are lagging indicators. They say nothing about:

    • System capability: How much throughput the system can sustain without extraordinary effort.
    • Resilience: How the system behaves under disruption – supplier failures, design changes, regulatory actions.
    • Execution risk: How much rework, delay, and compliance exposure is invisibly accumulating in the background.

    Execution systems matter because they directly control five operational realities:

    1. Flow of work
      Whether work moves smoothly through the factory and across suppliers, or stalls at hidden bottlenecks and queues.
    2. Quality outcomes
      Whether quality is built into the process via enforced standards and in-process checks, or inspected in later and reconstructed for audits.
    3. Traceability
      Whether every serialized component’s history is automatically captured, or must be pieced together from spreadsheets and paper.
    4. Change management
      Whether engineering changes propagate cleanly into production, or create configuration ambiguity and retrofit campaigns.
    5. Decision latency
      Whether leaders can see issues in hours, or discover them weeks later when they show up as missed deliveries or nonconformances.

    These factors are what ultimately determine whether a program is stable or fragile. They are independent of quarterly scoreboard performance – until the underlying weaknesses surface publicly.

    Key Systems, Processes, and Technologies in the Aerospace Execution Layer

    To understand how aerospace manufacturers move beyond the scoreboard, it helps to break down the major elements that make up a modern execution environment.

    1. ERP, MES, and the Reality Gap

    ERP (Enterprise Resource Planning) systems are optimized for planning, financial control, and high-level scheduling. They answer questions like:

    • What should we build, and when?
    • What is the demand plan and material requirement?
    • What is the cost and revenue profile for this program?

    They do not answer:

    • What is actually happening on line 3 right now?
    • Which work orders are blocked for quality, tooling, or missing components?
    • Where exactly is this serialized component, and what operations have been completed?

    MES (Manufacturing Execution Systems) and connected execution platforms bridge this gap by managing day-to-day, minute-by-minute execution:

    • Releasing work to the floor with the correct version of the process and instructions.
    • Capturing operator actions, measurements, and sign-offs.
    • Enforcing routing, sequence, and hold points.
    • Integrating with inspection, test, and calibration systems.

    The hub topic ERP vs MES vs Reality naturally emerges here: planning and transactional systems alone do not constitute an execution layer. Real execution lives closer to the work, and must be synchronized with ERP rather than replaced by it.

    2. Digital Thread and Production Traceability

    In aerospace, digital thread is often used as a buzzword. In operational terms, it means something very specific:

    A digital thread is the persistent, connected record that links requirements, design data, process definitions, execution events, quality records, and as-built configurations for every serialized product across its lifecycle.

    For production, the digital thread underpins traceability – the ability to answer, with evidence:

    • Exactly which material lots, components, and special processes were used on a given serialized aircraft component or assembly.
    • Which procedures, revisions, and tools were applied at each step.
    • Which nonconformances were detected, how they were dispositioned, and what rework was performed.

    In a mature execution environment, this traceability is embedded in the process, not reconstructed after the fact. Workflows, data capture, and sign-offs generate the digital thread as a byproduct of doing the work correctly.

    3. Industrial IoT in Aerospace Production

    Industrial IoT (IIoT) connects machines, tools, sensors, and test equipment to the digital execution layer. In aerospace, IIoT plays several critical roles:

    • Capturing process data from CNC machines, ovens, autoclaves, and test rigs to prove compliance with process specifications.
    • Monitoring key parameters (temperature, pressure, cycle time, vibration) in real time to detect drift before it becomes a nonconformance.
    • Tracking asset utilization, downtime, and bottlenecks to understand true throughput capability.

    IIoT data is most valuable when it is not isolated in dashboards, but contextualized within the execution system: tied to specific operations, work orders, serial numbers, and quality records.

    4. Aerospace Quality Management in the Execution Layer

    Traditional quality management in aerospace has often been document-centric and retrospective: procedures written in one system, records stored in another, audits performed by sampling and reconstruction.

    In a connected execution environment, quality is procedural and transactional:

    • Control plans and inspection requirements are directly tied to operations in the routing.
    • Inspection results are captured at the point of work and linked to serials and lots.
    • Nonconformances trigger controlled workflows, not ad hoc email chains.
    • Audit trails are generated automatically as work is performed.

    This shift is particularly important for small and mid-sized aerospace suppliers. Building audit readiness into everyday execution is far more sustainable than retrofitting compliance under customer or regulator pressure.

    5. Supplier Collaboration and Multi-Enterprise Execution

    No aerospace OEM operates alone. Programs depend on a network of suppliers whose performance directly affects backlog risk, delivery stability, and quality outcomes.

    A modern execution layer must therefore extend beyond the four walls of a single plant:

    • Sharing structured demand, configuration, and change data with suppliers.
    • Receiving real-time or near-real-time status on critical parts and assemblies.
    • Aligning process expectations, quality controls, and traceability requirements across the chain.

    Platforms like Connect 981 are emerging in this space as shared operational environments – not replacing each supplier’s internal systems, but connecting them into a coherent, multi-enterprise execution picture.

    How Aerospace Manufacturers Implement a Modern Execution Layer

    Most aerospace organizations do not start from a blank slate. They start from:

    • Existing ERP and PLM systems.
    • Legacy MES tools or internally built applications.
    • Spreadsheets, shared drives, and paper travelers.
    • Local workarounds on each line, cell, or site.

    Implementing a modern execution layer is less about wholesale replacement and more about systematically closing the gap between planning and reality. Common patterns include:

    1. Map the Current Execution Architecture

    Before adding technology, leading organizations take a disciplined inventory of their execution landscape:

    • Where does work instruction content come from, and how is it controlled?
    • How are routings and operation sequences defined and updated?
    • Where and how is production status tracked today (ERP, MES, spreadsheets, boards)?
    • How is quality data captured and linked to specific work orders and serials?
    • What do auditors ask for, and how is that evidence assembled?

    This mapping exercise often reveals multiple “shadow systems” that fill gaps between ERP and the shop floor – particularly around real-time status, traceability, and change management.

    2. Define the Digital Thread and Traceability Requirements

    Next, manufacturers clarify what traceability is actually required for their mix of products and customers:

    • Part-level vs assembly-level serialization.
    • Which characteristics and process parameters must be retained, and for how long.
    • What evidence regulators and customers expect for special processes, critical characteristics, and key characteristics.

    This prevents over-engineering generic solutions and focuses investment on high-value, high-risk flows – such as flight-critical components, safety-of-flight hardware, and complex assemblies with long service lives.

    3. Introduce Connected Work Execution

    A core building block is replacing fragmented travelers, local spreadsheets, and static work instructions with connected, version-controlled execution:

    • Digital work instructions linked to specific operations and revisions.
    • Electronic sign-offs tied to operator identity, timestamp, and station.
    • Integrated capture of measurements, images, and attachments as part of the workflow.
    • Automatic routing of holds, deviations, and nonconformances.

    This step alone begins to create a live operational picture: what is running, what is blocked, and why.

    4. Integrate Quality and Nonconformance Management

    Instead of treating quality as a separate system, manufacturers increasingly embed it within the execution layer:

    • Inspection points defined as operations, not footnotes.
    • Nonconformances triggered from within the work context, with relevant data pre-attached.
    • Disposition workflows aligned with engineering, MRB, and regulatory needs.
    • Built-in links from nonconformances to affected serials, lots, and downstream assemblies.

    This integrated approach reduces decision latency and improves the fidelity of lessons learned, feeding back into design and process improvements.

    5. Extend Visibility Across the Supply Chain

    As OEMs and tier-1s stabilize internal execution, attention turns outward:

    • Identifying critical suppliers where lack of visibility poses schedule or compliance risk.
    • Agreeing on a minimal, consistent status and traceability model.
    • Providing suppliers with lightweight, secure ways to participate in the shared execution picture.

    This is where multi-enterprise execution platforms, including Connect 981, begin to create network effects: each participant gains from a clearer view of upstream commitments and downstream dependencies.

    Common Challenges and Mistakes in Building Aerospace Execution Systems

    Even experienced aerospace organizations encounter predictable pitfalls as they mature their execution layer.

    1. Treating ERP as the Execution Solution

    One of the most common missteps is trying to stretch ERP into roles it was never designed for:

    • Using ERP screens as de facto operator interfaces.
    • Tracking process parameters and measurements as generic fields or attachments.
    • Relying on manual status updates in ERP to represent real-time shop floor conditions.

    This leads to brittle processes, workarounds, and a false sense of control. ERP remains essential for planning and financial control, but it is not the execution environment.

    2. Retrofitting Traceability Rather Than Designing It In

    Another recurring pattern is attempting to “add traceability” late in a program or under certification pressure:

    • Scanning paper travelers into document repositories.
    • Rebuilding as-built histories from mixed digital and manual records.
    • Deploying point solutions that capture data but do not integrate with work execution.

    This retrofitting is expensive, error-prone, and fragile. It often fails under the stress of an investigation, major audit, or in-service event. Sustainable traceability must be designed into the execution process from the start.

    3. Confusing Reporting with Real-Time Visibility

    Aggregated reports and dashboards are useful, but they are not the same as real-time operational control:

    • Reports describe what happened; visibility shows what is happening now.
    • Reports aggregate; visibility connects detail to context (which serial, which station, which operator).
    • Reports support review; visibility supports intervention.

    Organizations that stop at reporting often find that issues are identified only after they have already impacted deliveries or quality metrics.

    4. Underestimating Engineering Change Impact

    In aerospace, engineering changes propagate through long-running programs and complex, serialized fleets. A weak execution layer struggles to:

    • Ensure that only the correct revision of a process or drawing is used at each operation.
    • Identify which in-progress or completed units are affected by a given change.
    • Coordinate rework, retrofit, or concessions across sites and suppliers.

    Without a connected execution layer and clear digital thread, change management becomes a major source of backlog risk and rework cost.

    5. Ignoring Small Suppliers in the Execution Strategy

    OEMs and tier-1s sometimes invest heavily in internal systems while assuming smaller suppliers will “keep up” via email and portals. This creates systemic fragility:

    • Suppliers struggle with disconnected tools and manual compliance work.
    • Critical status information arrives late or in inconsistent formats.
    • Audit readiness depends on heroic reconstruction efforts at the supplier level.

    Bringing small and mid-sized aerospace suppliers into a shared execution model – with appropriately sized tools and processes – is often the difference between theoretical and actual supply chain resilience.

    Future Trends: Where Aerospace Execution Systems Are Heading

    The industry is quietly but decisively moving beyond scoreboard metrics toward deeper execution maturity. Several trends are accelerating this shift.

    1. From Program-Level KPIs to System Capability Metrics

    Executives are beginning to ask different questions:

    • What is our stable throughput capability at each major node, not just last quarter’s deliveries?
    • How much rework, scrap, and unplanned overtime did it take to hit those numbers?
    • How quickly do we detect and contain quality issues, and at what stage?

    This leads to new metrics grounded in execution rather than outcomes: flow efficiency, first-pass yield at key operations, deviation and concession rates, mean time to detect and resolve issues, and audit finding recurrence.

    2. Normalizing the Concept of a Multi-Layer Digital Architecture

    Aerospace organizations are increasingly adopting an explicit architecture view, consistent with standards like ISA-95 and industry best practices:

    • Level 4: ERP, program management, financials.
    • Level 3: MES and execution platforms (where Connect 981 operates).
    • Level 2: Supervision, SCADA, and IIoT connectivity.
    • Level 1/0: Machines, tools, sensors, and physical processes.

    Clarity about what lives where – and how data flows between levels – reduces duplication, integration risk, and project failure modes.

    3. Execution-Centric Digital Threads

    Digital thread initiatives are evolving from repository projects to execution-centric models. Instead of trying to link every possible artifact, leading organizations focus on:

    • Anchoring the thread in actual work execution events.
    • Ensuring each critical part and assembly has a complete as-built record.
    • Making that record queryable by serial, configuration, and time to support investigations and continuous improvement.

    This pragmatism makes the digital thread operational, not just conceptual.

    4. Audit-Ready by Default

    A particularly important shift for smaller aerospace suppliers is the move toward being “audit-ready by default”:

    • Every work order execution leaves a complete, consistent, and accessible digital footprint.
    • Documentation packages can be generated on demand, not assembled by hand.
    • Customer and regulator questions can be answered directly from the execution system, not from reconstructed archives.

    Suppliers that build this capability early gain a structural advantage: they can handle increased volume and scrutiny without proportionally increasing overhead.

    5. The Rise of the Aerospace Execution Layer as a Distinct Category

    Finally, the industry is starting to recognize the execution layer as a distinct system category – separate from ERP, PLM, and traditional plant-floor tools. This layer:

    • Connects planning intent to physical reality in real time.
    • Provides the operational truth that scoreboard metrics lag.
    • Spans organizational boundaries, from OEMs to the smallest critical supplier.

    Connect 981 is part of this emerging category. It does not replace ERP, PLM, or existing machines and tools. It connects them into a coherent, controllable execution environment tailored to the realities of aerospace manufacturing.

    Connecting the Knowledge Hub to the Wider Aerospace Execution Conversation

    This hub provides the structural overview: why the aerospace scoreboard misleads, what an execution layer is, and how systems like MES, IIoT, quality workflows, and digital threads fit together within the Connect 981 ecosystem.

    Surrounding it are deeper dives that explore key dimensions of this shift:

    • Backlog as Execution Liability – reframing aircraft backlog as a long-term execution and supply chain risk profile, not just a demand indicator.
    • Deliveries vs Throughput – distinguishing headline output metrics from true system capability and flow.
    • Why ERP Isn’t Enough – clarifying the limits of planning systems in regulated aerospace environments.
    • MES vs ERP vs Reality – mapping where execution actually lives, and how ISA-95-style thinking applies in aerospace.
    • Digital Thread in Aerospace – cutting through buzzwords to define an execution-grounded digital thread.
    • Audit-Ready Small Suppliers – practical steps for SMEs to embed compliance and traceability into everyday work.
    • Real-Time Production Visibility – what it looks like when visibility moves from reports to live operational awareness.
    • Why Traceability Retrofitting Fails – lessons from attempts to bolt on traceability under pressure.
    • Supply Chain Resilience and Execution – how shared execution views improve aerospace network stability.
    • Engineering Change and the Execution Gap – controlling change impact through the execution layer.
    • Digital Manufacturing Architecture for Aerospace – designing a coherent, multi-layer architecture with the execution layer at its core.

    Each of these themes can stand alone but also loops back to the same conclusion: aerospace performance is determined less by the scoreboard and more by how well an organization can see, coordinate, and control execution across its entire manufacturing ecosystem.

    As this cluster of thinking expands, the role of Connect 981 becomes clearer – not as another metric generator, but as the connective tissue that turns data, processes, and partners into a functioning execution system for aerospace manufacturing.

  • What Aircraft Backlog Really Means: Execution Liability in Aerospace Programs

    What Aircraft Backlog Really Means: Execution Liability in Aerospace Programs

    In most aerospace headlines, a growing aircraft backlog is treated as proof of strength. Years of production already sold. Market share locked in. A reassuring signal to investors and boards that demand is secure.

    But in regulated aerospace and defense manufacturing, backlog is not just a demand metric. It is a time-distributed execution liability: a stack of promises that must be converted into certified, conforming hardware under changing regulatory, supply chain, and design conditions.

    For teams putting this topic into daily operation, Connect 981’s aerospace execution solutions help connect the concept to traceability, work-order reality, and audit-ready evidence.

    For teams putting this topic into daily operation, execution systems for aerospace manufacturing, shop floor execution control help connect the concept to traceability, work-order reality, and audit-ready evidence.

    The same operating model also depends on a connected execution platform, Connect 981’s aerospace operations guidance, practical aerospace operations FAQs, closing the Engineering Change Execution Gap, especially when decisions have to move across quality, production, suppliers, and program leadership without losing context.

    In the aerospace scoreboard critique, we argued that deliveries, revenue, and backlog tell only a thin story about program health. This article goes deeper on backlog specifically: what actually lives inside those numbers, why they can mask operational fragility, and how a connected execution layer changes how you read and manage backlog risk.

    Why Backlog Is Misunderstood in Aerospace

    The traditional narrative: backlog as proof of market dominance

    On the surface, backlog is simple: customer orders that have been contractually secured but not yet delivered. A large backlog suggests strong demand, pricing power, and predictable future revenue. In commercial aviation, it is often discussed as “years of production at current rates.”

    For aerospace leaders, that narrative is only partially useful. A 10-year backlog on a major aircraft family does not just represent revenue; it encodes:

    • Capacity assumptions across OEM final assembly, major structures, and critical systems
    • Supplier health and capital investment that has not yet occurred
    • Future labor, skills, and certification requirements that will move over time
    • Configuration and variant complexity that may not be fully visible today

    Seen this way, backlog is less a trophy and more a long-duration constraint problem. You are not just selling airplanes; you are committing your entire industrial system to a specific future.

    Why long program lifecycles distort backlog meaning

    Aerospace programs routinely span decades. A backlog booked today may convert into deliveries five, ten, or even twenty years from now, crossing multiple regulatory regimes, technology refresh cycles, and macroeconomic environments.

    This time scale distorts traditional interpretations of backlog:

    • Forecast horizons are inherently uncertain. Demand, route structures, and fleet strategies shift faster than hardware can be designed and certified.
    • Industrial footprints evolve. Sites open, consolidate, or retool, changing where and how backlog will actually be executed.
    • Regulatory expectations increase over time. What was acceptable five years ago may require deeper traceability and configuration control when a later backlog tranche is built.

    As a result, the further out backlog extends, the more it should be seen as a risk portfolio, not a fixed promise that the current system can easily fulfill.

    How regulated environments amplify backlog uncertainty

    Unlike many industrial sectors, aerospace, defense, and space hardware operate under tight certification, export, and quality regimes. Every aircraft in the backlog is not just a unit of demand; it is a unit of regulatory exposure.

    Long backlogs magnify questions such as:

    • Will today’s process qualifications, suppliers, and special processes still be approved and available at the time of build?
    • Can we demonstrate uninterrupted traceability and configuration control across design changes, supplier transitions, and rate increases?
    • What happens to backlog scheduling if a key supplier faces an audit issue, or a quality escape halts a production line?

    Without a clear execution layer connecting backlog commitments to live production and supplier data, these questions are often answered with static assumptions, not operational evidence.

    What Actually Lives Inside an Aircraft Backlog

    Execution risk over 5–20 year horizons

    Each line in an aircraft backlog is a multi-year execution plan hidden inside a financial metric. That plan spans design maturity, industrialization, ramp-up, steady-state production, and eventual rate changes or sunset strategies.

    Over a 5–20 year horizon, the underlying execution risk accumulates from multiple sources:

    • Process drift: Work instructions, routings, and inspection plans evolve. If these changes are not tightly controlled and connected to the digital thread, you risk building later backlog under a process definition that no longer matches certification intent.
    • Knowledge loss: Critical know-how sits with individuals and local teams. As staff rotates, tribal knowledge gaps can transform a stable line today into a fragile one later while the backlog number appears unchanged.
    • Unmodeled dependencies: Test equipment, tooling, and special process capacity that nobody explicitly tied to backlog volumes when the contracts were signed.

    The longer the horizon, the more your backlog becomes a bet on your ability to keep execution aligned with intent under constant change.

    Supplier stability and capacity constraints

    Most aircraft content is produced in the supply chain, not inside OEM final assembly buildings. A large backlog therefore implies that hundreds or thousands of suppliers will sustain certified, capable production for many years.

    Execution exposure hides in questions such as:

    • How many critical parts are effectively single-sourced due to qualification complexity or unique processes?
    • Where does current quality performance already suggest that a supplier will struggle at higher rates?
    • Are there sub-tiers (forgings, castings, specialized treatments) whose constraints are invisible in OEM-level planning?

    Without integrated supplier traceability and production visibility, backlog implicitly assumes that supplier networks will behave as modeled, even when factory reality is already signaling issues.

    Regulatory, certification, and design change exposure

    Backlog is booked against a program baseline, but that baseline is rarely static. Over a 10-year horizon, you can expect block changes, service bulletins, weight reduction efforts, performance upgrades, and regulatory-driven modifications.

    Each change creates variants in the backlog:

    • Different configurations for different operators and missions
    • Retrofit and modification work scopes interwoven with new production
    • Multiple software loads and hardware revisions that must remain tightly correlated

    If your configuration management and digital thread are not robust, the backlog number obscures a growing set of execution paths, each with its own risk profile and certification obligations.

    Contractual commitments versus real production capability

    Commercial and defense contracts typically embed schedule, performance, and availability commitments based on a model of what the industrial system can do. When that model is optimistic, backlog becomes a liability.

    Common gaps include:

    • Assumed learning curves that do not match actual ramp-up behavior on the shop floor
    • Underestimated non-conformance and rework that quietly consumes capacity needed for future backlog
    • Planned automation or capital projects that slip or under-deliver, leaving manual processes in place longer than expected

    The more your backlog is decoupled from live execution data, the greater the risk that contractual commitments drift away from what your factories and suppliers can reliably deliver.

    Backlog as a Supply Chain Stress Test

    How tiered supplier networks absorb (or fail to absorb) demand

    Every time you publicize a multi-year backlog figure, you are implicitly stress-testing your supplier network. The question is not just “Can we build this many aircraft?” but “Can every critical tier absorb and sustain this load?”

    In practice, backlog acts like a slow-motion stress test:

    • Tier 1 integrators must align capital spending and staffing with the projected demand profile.
    • Tier 2 and Tier 3 providers of forgings, machined parts, composites, and electronics must decide whether to invest based on partial or lagging visibility.
    • Special process houses must balance aerospace work against other regulated industries with different demand cycles.

    When that coordination is weak, backlog converts into late deliveries, expediting, and reactive rescheduling instead of predictable output.

    The impact of single-source and specialty process suppliers

    In many programs, a small number of suppliers control disproportionate leverage because they operate certified special processes, build key structures, or own legacy intellectual property. Your backlog is only as executable as their capacity, quality system, and financial health allow.

    Execution risk intensifies when:

    • Critical processes (e.g., heat treatment, bonding, coating) exist at only one or two approved sites.
    • Qualification of alternates takes years and ties up engineering and certification capacity.
    • Supplier quality data is siloed, so systemic issues become visible only after they constrain production.

    Without a shared execution layer that exposes real-time performance, work-in-process, and non-conformance patterns, backlog reporting will overstate how robust those bottleneck nodes actually are.

    Backlog concentration by program, platform, and customer

    Backlog is rarely evenly distributed. It clusters around specific platforms, engine choices, cabin options, and customer fleets. That concentration matters operationally.

    For example:

    • A heavy concentration of a single high-complexity variant may strain particular work cells and inspection resources.
    • Backlog tied to a few fleet operators can drive irregular modification and retrofit campaigns that ripple into new production schedules.
    • Defense contracts with option years can rapidly increase demand on specific configurations if exercised unexpectedly.

    These patterns do not show up in a headline backlog number, but they have direct implications for line balancing, staffing, and supplier scheduling.

    How OEM Metrics Hide Backlog Quality

    Backlog value versus backlog executability

    Financial reporting emphasizes backlog value: the aggregate revenue associated with firm orders and, in some cases, options or letters of intent. From an execution perspective, a more relevant dimension is backlog executability—the probability that each unit can be delivered on time, at cost, and in compliance given the state of your system.

    Two aircraft programs might report similar backlog values but have very different execution profiles because of:

    • Higher design churn and immature configurations
    • Less stable suppliers or greater exposure to constrained commodities
    • Weaker production visibility and fragmented traceability

    Without metrics that explicitly connect backlog to operational capability, dashboards can look strong while factories operate at the edge of control.

    Cancellation, deferral, and reprioritization dynamics

    Backlog is not static. Airlines and operators cancel, defer, or swap slots as their own strategies evolve. Defense customers adjust profiles around funding cycles and mission needs. On paper, net backlog may appear stable even as the internal profile becomes more complex.

    Operationally, this creates churn:

    • Final assembly lines must adapt to variant mixes that were not originally planned.
    • Suppliers must reshuffle production sequences while protecting lead times and shelf-life-limited materials.
    • Configuration management and planning teams must keep bills of material and routing definitions synchronized with shifting demand.

    If these dynamics are not connected directly into an execution layer that updates work orders, material reservations, and inspection plans, the risk of misbuilds and delays increases while backlog reports remain deceptively calm.

    Why paper stability can mask operational fragility

    A program can report a steady backlog, steady deliveries, and stable revenue while living with high rework, extensive out-of-station work, and frequent schedule recovery actions. The system is fragile but still producing outputs that look healthy in aggregate.

    Common indicators of this hidden fragility include:

    • Heavy reliance on offline spreadsheets to track real production status
    • Traceability reconstructed for audits rather than captured inline with work
    • Quality escapes that are found late, triggering quarantines and travel work

    Backlog, by itself, has no way to reveal these patterns. Only real-time production visibility and integrated quality data can distinguish between a system that is truly in control and one that is barely keeping up with paper commitments.

    Managing Backlog as Deferred Execution Risk

    Translating backlog into capacity and capability requirements

    To treat backlog as a managed risk, you need to translate financial units into operational units. That means asking, for each significant slice of backlog, “What specific capacity and capability must exist, where, and when?”

    Practically, this translation involves:

    • Breaking backlog down by configuration, major assembly, and key options.
    • Mapping those units onto actual lines, work cells, and suppliers.
    • Identifying which stations, processes, and certifications are rate-limiting for each profile.

    This reframes backlog planning from a volume problem to a networked capability problem, which can then be monitored and adjusted as live data comes in.

    Using real-time production visibility to validate backlog assumptions

    Most backlog plans are built from models and historical performance. As production ramps, those assumptions must be challenged with live data from factories and suppliers.

    An effective execution layer enables:

    • Cycle time and WIP visibility at the operation level, not just at the aircraft or shipset level.
    • Real-time constraint identification based on queues, overtime, and non-conformance patterns.
    • Automated feedback loops that flag when assumed rates or yields no longer match observed performance.

    When that visibility is connected back to backlog views, leaders can distinguish between segments of backlog that are operationally supported and those that are already at risk.

    Scenario planning with integrated supplier data

    Scenario planning around backlog—rate increases, customer mix changes, new variants—only becomes meaningful when supplier data is part of the picture. That means going beyond high-level capacity declarations to include actual performance, constraints, and material flows.

    With an integrated execution layer that connects OEM production systems to supplier status, you can simulate, for example:

    • How a 20% rate increase on one program propagates through shared suppliers and special processes.
    • What backlog segments become vulnerable if a key supplier slips by two weeks on average.
    • How configuration changes would affect tooling, inspection resources, and first article workloads at each tier.

    This shifts scenario planning from spreadsheet exercises to model-based operational planning grounded in current data.

    Aligning quality and configuration control with backlog horizon

    Quality systems and configuration management are often treated as compliance domains, but they are central to backlog executability. Over a long horizon, even small misalignments can compound into major schedule risk.

    Key practices include:

    • Ensuring that non-conformance trends are linked back to specific backlog segments and configurations, not just aggregated at program level.
    • Maintaining a continuous digital thread so that every aircraft in the backlog can trace forward to how it should be built and backward to the design and process assumptions that justify it.
    • Embedding configuration checks in the execution workflow, so that as options, blocks, and change notices evolve, shop-floor work instructions and inspection plans remain synchronized.

    When quality and configuration control are integrated into daily execution, the long tail of backlog becomes more predictable and auditable.

    The Role of a Connected Execution Layer

    Connecting ERP backlog to actual factory status

    ERP systems are effective at capturing contracts, orders, and planned schedules. They are not designed to reflect minute-by-minute factory reality: which jobs are truly started, where WIP is held, which operations are blocked by missing parts or non-conformances.

    A connected execution layer fills that gap by:

    • Tracking production status at the operation and unit level across lines and cells.
    • Associating each work step with material lots, serial numbers, inspection results, and operator actions.
    • Feeding summarized status and risk signals back to planning systems that manage backlog and order books.

    Platforms like Connect 981 operate in this space—not replacing ERP, but making its backlog and schedule constructs reflect what is actually happening on the factory floor.

    Surfacing supplier constraints early through shared visibility

    Many backlog failures originate outside OEM walls. A connected execution layer that extends into the supply chain can surface constraints long before they become delivery crises.

    With shared production visibility between OEMs and key suppliers, you can:

    • See real WIP positions and queue times at critical suppliers.
    • Identify chronic non-conformance loops that point to process capability issues.
    • Align backlog-driven demand profiles with supplier capacity decisions based on operational evidence, not just forecasts.

    This turns backlog from a set of static promises into a joint execution plan, continuously adjusted as conditions change.

    Linking backlog changes to digital thread and traceability

    Backlog evolves: customers switch options, regulators issue new guidance, engineering introduces cost or performance improvements. Each of these changes has implications for the digital thread and traceability obligations.

    A robust execution layer connects these domains by:

    • Ensuring that changes to backlog configuration are reflected in bills of material, routings, and inspection plans.
    • Capturing part genealogy and process data automatically as work occurs, so that variants and block changes remain fully traceable.
    • Providing a single operational view where engineering, quality, and production can see how backlog changes translate into actual work orders and hardware.

    This reduces the risk that late design changes or option swaps create hidden compliance or rework exposure in later backlog deliveries.

    Why platforms like Connect 981 sit between contracts and reality

    The distance between an order booked in ERP and a conforming aircraft on the flight line is where most execution risk lives. Traditional systems of record capture intent and history, but they do not orchestrate the day-to-day conversion of backlog into hardware across multiple organizations.

    A platform such as Connect 981 is designed to inhabit that space: the execution layer between contracts and reality. By integrating production visibility, traceability, and supplier coordination, it allows aerospace manufacturers to read backlog as an operational signal, not just a financial metric, and to intervene early when the system’s ability to deliver diverges from what the backlog implies.

    Reading Backlog Correctly: Questions Aerospace Leaders Should Ask

    Which parts of our backlog are execution-limited today?

    Instead of treating backlog as a monolithic number, segment it by program, configuration, and supplier exposure, then ask where you are already constrained. Look for evidence in cycle times, rework rates, supplier misses, and the amount of manual coordination required to hit schedule.

    The goal is to identify backlog segments that are rate-limited by specific bottlenecks or immature processes, then focus improvement and investment where it changes actual deliverability rather than headline figures.

    Where are we blind to supplier and configuration risk?

    Every gap in visibility between OEM systems and supplier operations is a place where backlog assumptions can silently decay. Likewise, every manual handoff in configuration management is an opportunity for mismatch between what was sold, what was planned, and what is built.

    Map where you rely on static declarations or periodic reports instead of live data, and where configuration changes are applied through email or spreadsheets rather than system-enforced workflows. Those are the blind spots that turn backlog into sudden crises.

    How would our view of backlog change with live execution data?

    Finally, consider how your backlog conversations would shift if every key stakeholder could see the same real-time operational picture: station status, WIP positions, supplier queues, non-conformance hotspots, and configuration variants in work.

    In that environment, backlog stops being a celebratory number on a slide and becomes an input to continuous coordination. The question is no longer “How big is our backlog?” but “How well is our system positioned today to execute the backlog we have?” That is the question aerospace leaders ultimately need to answer.

  • Deliveries vs. Throughput: Why Aerospace Output Metrics Mislead

    Deliveries vs. Throughput: Why Aerospace Output Metrics Mislead

    In aerospace, delivery numbers dominate headlines and executive reviews. Monthly and yearly totals are easy to understand and easy to compare. But if you are responsible for an aircraft, missile, or space hardware production line, you already know the problem: deliveries say almost nothing about how hard the system had to work to ship that hardware, or whether it can do it again next month.

    The core issue is the same one explored in the misleading aerospace scoreboard: we are using surface-level output metrics to judge systems that are fundamentally constrained by complexity, regulation, and coordination. If you manage an AS9100 production environment, you need a different scoreboard—one that measures throughput, flow, and system health instead of just deliveries.

    For teams putting this topic into daily operation, execution systems for aerospace manufacturing, shop floor execution control, a connected execution platform help connect the concept to traceability, work-order reality, and audit-ready evidence.

    The same operating model also depends on Connect 981’s aerospace execution solutions, real aerospace execution examples, Connect 981’s aerospace operations guidance, practical aerospace operations FAQs, especially when decisions have to move across quality, production, suppliers, and program leadership without losing context.

    Why Delivery Counts Dominate the Aerospace Narrative

    The visual appeal of delivery charts

    Delivery charts are compelling because they compress a complicated story into a single line. Executives can see trends at a glance. Investors can compare OEMs. Programs can be ranked and benchmarked. A rising line signals momentum; a falling line triggers concern.

    Inside factories and across the supply chain, these same charts shape behavior. Teams feel pressure to “hit the number” by quarter-end. Ship dates become fixed reference points, even when upstream realities are changing daily. The simplicity of deliveries makes them attractive, but that simplicity comes with cost: almost all context is stripped away.

    Investor communication reinforces delivery obsession

    Public aerospace companies rely on delivery counts as one of the few operational metrics that can be disclosed consistently across programs and time. Analysts model revenue and cash flow around shipments. Backlog and deliveries become shorthand for competitiveness.

    This external framing seeps back into internal management. Senior leaders report deliveries upward, so functional teams naturally optimize for them. But an AS9100-regulated factory is not a commodity volume line. The effort required to ship one serial number can vary by orders of magnitude, depending on design maturity, supplier stability, and quality status. When all of that nuance is collapsed into a single count, the delivery number becomes a distorted lens rather than a clear one.

    Why deliveries are only a partial view of performance

    A delivery record tells you that a configuration passed a specific gate at a specific time. It does not tell you:

    • How many hours of rework, repair, and concessions review were required.
    • How many units of work-in-process (WIP) were tied up or cannibalized to complete that shipset.
    • How many engineering changes or deviations were pushed through under schedule pressure.
    • Whether the underlying flow is stable and repeatable, or a one-off surge effort.

    Two factories can both ship 10 aircraft in a month. One may do so with high first-pass yield, predictable cycle times, and low overtime. The other may rely on firefighting, expediting, and hidden backlog. The delivery count is identical; the production systems are not.

    Defining Throughput in Regulated Aerospace Manufacturing

    Throughput versus takt in low-volume, high-complexity work

    In high-mix aerospace environments, true throughput is not simply “units per hour.” It is the rate at which conforming, configuration-correct hardware moves through the value stream over time. That rate is constrained by:

    • Engineering release and configuration maturity.
    • Special processes and certified operations.
    • Non-destructive testing and acceptance testing capacity.
    • Supplier capability and lead time.

    Unlike high-volume industries, takt time is rarely a single fixed number. Different work centers operate on different cadences, with long dwell times around inspections and tests. Measuring throughput requires looking at the whole flow across cells, not just a nominal cycle time at a single station.

    Accounting for inspection, testing, and certification steps

    Regulated aerospace production inserts multiple non-optional steps into the flow: in-process inspection, functional test, environmental test, flight test, conformity checks, and regulatory or customer acceptance. Each of these can become a limiting constraint, particularly when demand fluctuates or when a quality escape triggers additional sampling.

    Throughput therefore must be measured across these verification gates, not just across assembly operations. A line that can mechanically assemble hardware quickly but waits days or weeks for test capacity does not have high throughput. It has local speed and system-level delay.

    How rework and concessions distort perceived throughput

    Rework is where the disconnect between deliveries and real throughput becomes most obvious. A unit that passes final inspection after three major rework cycles shows up as a single delivery. In the system, though, it consumed the equivalent capacity of multiple units:

    • Additional touch labor and quality engineering support.
    • Extra MRB (Material Review Board) and concession processing.
    • Retesting, re-inspection, and documentation updates.

    Concession-heavy programs can appear to be delivering acceptably while quietly burning massive capacity on hidden work. Without metrics that distinguish first-pass throughput from total output, leadership cannot see the erosion of real capability until it is severe.

    Hidden Work Behind a Single Delivery

    Non-conformances, deviations, and repair loops

    Every major aerospace program carries a tail of non-conformances and deviations. A single shipset might involve dozens of quality records across subassemblies, hardware substitutions, and process deviations. Each record requires investigation, root cause analysis, and documented disposition.

    On the shop floor, this translates into repair loops: units leave the main line, move to rework areas, wait on engineering or supplier input, and eventually return for retest and reintegration. From a delivery perspective, all of this collapses into a single date. From a throughput perspective, it represents a major diversion of flow and capacity.

    Supplier-driven delays and expediting behaviors

    Suppliers introduce another layer of hidden work. When critical components arrive late, out of tolerance, or incomplete, internal teams respond by:

    • Resequencing work to keep technicians utilized.
    • Partial building and kitting around missing items.
    • Expediting shipments and engineering dispositions.
    • Cannibalizing parts from other WIP to close a near-term delivery.

    These tactics protect the delivery schedule in the short term, but they damage throughput. Flow becomes unpredictable, WIP grows in odd places, and future deliveries inherit the disruption. Without a clear view of these patterns, leaders may misinterpret on-time delivery as evidence of a healthy system when it is actually the result of unsustainable expediting.

    Paperwork and traceability reconstruction effort

    In AS9100 environments, paperwork and digital traceability are as important as physical build status. When travelers, inspection records, or certificates of conformance are incomplete, teams often scramble near ship dates to reconstruct the digital thread.

    This reconstruction work rarely appears explicitly in any metric. Engineers and planners dig through email, shared drives, and spreadsheets to close gaps. The unit ships; the delivery target is met. But the underlying system is signaling a problem: execution and traceability are not aligned. True throughput should account for this late-stage effort, because it represents real cost and risk.

    Metrics That Reveal True Capability

    First-pass yield and right-first-time rate

    First-pass yield (FPY) measures the percentage of units that complete a process or flow without requiring rework. In aerospace, you can define FPY at multiple levels: operation-level, cell-level, or end-to-end configuration-level. High FPY indicates that work instructions, training, tooling, and design stability are aligned.

    Right-first-time rates are powerful because they convert quality into a flow metric. A line that delivers 95% of units right-first-time has far more real capacity than one that delivers the same total output but with 60% FPY. Dashboards that highlight FPY by constraint area let teams attack the factors that erode throughput long before delivery numbers slip.

    Queue times versus touch times across operations

    Touch time is how long a technician, inspector, or operator is actively working on a unit. Queue time is how long that unit is waiting—for materials, paperwork, quality sign-off, engineering decisions, or test slots. In many aerospace factories, queue time dwarfs touch time.

    Measuring both is essential. You may discover that a critical assembly spends 80% of its lead time waiting between operations or sitting in front of a single constrained special process. Improving documentation flow or decision turnaround at those points can increase throughput without adding headcount or equipment.

    WIP aging, bottleneck analysis, and constraint tracking

    Healthy systems limit WIP and keep it moving. When WIP ages—units sit in the same status for days or weeks—it signals a flow break. Tracking WIP aging by operation, shop, and supplier reveals where the system is actually constrained.

    Bottleneck analysis in aerospace is more dynamic than in simple lines. Constraints move between internal cells, external suppliers, test facilities, and engineering. A robust metric set tracks where the constraint is this week, how much capacity it has, and how variability is affecting it. That is the level of visibility required to convert schedule promises into actual throughput.

    Lead time stability under schedule variation

    Throughput is not just about average speed. It is about predictability. In a constrained, regulated environment, a stable 14-week lead time may be healthier than a nominal 10-week lead time that routinely fluctuates between 8 and 20 weeks.

    Measuring lead time stability—for example, via standard deviation or on-time-complete metrics across internal milestones—gives you a truer sense of capability than delivery counts alone. Customers and program managers can plan around a stable system; unstable throughput forces constant replanning and erodes trust.

    Why Traditional Systems Struggle to Measure Flow

    Limitations of ERP-based completion reporting

    ERP systems are optimized for planning and financial posting, not for real-time execution. They know what should have happened, which operations are planned, and when a work order is financially complete. But they often lack granular timestamps, partial completions, or rich status reasons for delay.

    The result is a binary view of the world: not started, in process, complete. That may be enough for material requirements planning, but it is insufficient for understanding true throughput. The system does not natively distinguish a unit smoothly moving through flow from one oscillating between rework, MRB, and waiting on engineering.

    Gaps in MES coverage across mixed-model and manual work

    Many aerospace manufacturers have implemented MES systems for specific lines or processes, often around automated equipment or final assembly. But coverage is rarely universal. Manual, mixed-model, and prototype work frequently lives outside MES in travelers, whiteboards, and local databases.

    These gaps fragment the execution picture. You may have good visibility in a test cell, but no structured data on how long units waited for that test or how many were diverted to repair before arriving. Without end-to-end coverage, throughput and flow metrics become partial and misleading.

    The role of spreadsheets and manual status boards

    To compensate, teams build their own visibility layers: spreadsheets for WIP tracking, PowerPoint-based status boards, and informal messaging channels. These tools are flexible and fast to change, but they are also fragile and non-authoritative.

    From a metrics standpoint, manual layers break the digital thread. You cannot reliably compute FPY, WIP aging, or constraint utilization from a set of unlinked spreadsheets and hallway conversations. At best, you get snapshots; at worst, you get conflicting versions of reality across engineering, production, and quality.

    Using a Connected Execution Layer to See Throughput Clearly

    Real-time operation status and WIP tracking

    A connected execution layer fills the gap between planning systems and the shop floor. It does not replace ERP or existing MES where they work well. Instead, it connects work orders, operations, and quality events into a coherent, real-time view of WIP.

    In practice, this means every unit or serial number carries a live status: where it is, what operation it is on, who is working it, and what it is waiting on. With that foundation, throughput metrics are no longer estimates. You can see exactly how many conforming units are crossing key gates per day, week, or month and how that rate changes as conditions shift.

    Linking non-conformances and rework to flow metrics

    When quality events are integrated into the same execution layer, non-conformances, concessions, and repairs become part of the flow picture instead of being tracked separately. Each quality record is attached to specific work, operations, and components.

    This enables new metrics: rework hours per shipped unit, FPY by operation and configuration, and the impact of specific defect modes on overall throughput. Leaders can identify which recurring issues are eroding capacity and prioritize corrective actions based on system-wide impact, not just defect count.

    Visualizing constraint movement across suppliers and cells

    A connected execution layer can also extend beyond a single site. When suppliers participate—even with limited, well-scoped data sharing—you can visualize where work is actually piling up: internal assembly, external machining, special processes, or test labs.

    Rather than treating supplier delivery performance as a black box, you see WIP stages, queues, and cycle times in aggregate. This supports more productive conversations: instead of demanding “faster deliveries,” OEMs and tier-ones can collaborate with suppliers on specific constraint relief that improves throughput for both sides.

    Aligning engineering, quality, and production around shared data

    In many aerospace organizations, each function has its own view of performance. Engineering tracks change implementation. Quality tracks findings and audits. Production tracks schedule adherence. Without a shared execution layer, these views diverge and debates about “what is really happening” consume time.

    When all three functions work from the same operational data—live WIP, integrated quality events, and configuration-aware status—the conversation changes. Instead of arguing about numbers, teams can focus on constraints, trade-offs, and systemic improvements that raise real throughput.

    Redesigning the Aerospace Scoreboard Around System Health

    Balancing deliveries with stability and predictability metrics

    Deliveries will always matter. Customers, warfighters, and mission operators depend on them. The goal is not to dismiss delivery metrics, but to put them in the right context. A modern aerospace scoreboard balances:

    • Delivery performance (on-time, by configuration and customer).
    • Throughput at key gates (first-pass and total).
    • FPY and rework intensity at constraints.
    • Lead time stability and WIP aging.

    When these metrics move together, you know the system is getting healthier. When deliveries improve while FPY and stability worsen, you know you are borrowing from the future.

    Setting leading indicators for execution maturity

    Throughput metrics can also serve as leading indicators of execution maturity. Examples include:

    • Percentage of WIP with real-time status versus manual tracking.
    • Share of quality events initiated at the point of work versus discovered downstream.
    • Time from defect detection to containment and disposition.
    • Proportion of work covered by a connected execution layer.

    These indicators do not show up on investor slides, but they predict whether the system can handle increased rate, new configurations, or regulatory scrutiny without breaking.

    How OEMs can communicate capability without oversimplifying

    Externally, aerospace organizations face a tension: markets want simple numbers; operations need nuanced ones. The path forward is not to publish every internal metric, but to frame deliveries and backlog as outcomes of an execution system—and to explain how that system is being strengthened.

    That might mean discussing investments in connected execution, traceability, and supplier integration as part of program updates, or highlighting improvements in stability and right-first-time performance alongside shipment counts. Over time, the industry can move away from a one-dimensional scoreboard and toward a more accurate understanding of what real capability looks like in regulated aerospace manufacturing.

    For manufacturers across the supply chain, the underlying message is consistent: if you rely on deliveries alone to judge performance, you will miss the early signals. Throughput, flow, and system health live in the execution layer—and that is where competitive advantage is now being built.

  • Why ERP Isn’t Enough for Aerospace Manufacturing Execution

    Why ERP Isn’t Enough for Aerospace Manufacturing Execution

    Why ERP Isn’t Enough for Aerospace Manufacturing Execution

    Most aerospace manufacturers rely on an ERP system as the backbone of their business. It holds contracts, materials requirements, routings, costs, and schedules. On paper, it looks like the system that should tell you everything about the factory.

    In reality, it doesn’t. ERP is fundamentally a planning and transactional engine, not an execution environment. It models what should happen. It does not reliably show what is happening now on a specific line, cell, or work center.

    For teams putting this topic into daily operation, Connect 981’s aerospace execution solutions help connect the concept to traceability, work-order reality, and audit-ready evidence.

    For teams putting this topic into daily operation, execution systems for aerospace manufacturing, shop floor execution control help connect the concept to traceability, work-order reality, and audit-ready evidence.

    The same operating model also depends on ERP, MES, and PLM integration paths, a connected execution platform, Connect 981’s aerospace operations guidance, practical aerospace operations FAQs, especially when decisions have to move across quality, production, suppliers, and program leadership without losing context.

    The result is the familiar pattern across aerospace: program managers, production leaders, and quality teams spend their days reconciling ERP data with spreadsheets, whiteboards, emails, and walk-arounds. The system of record and the system of reality are different things.

    This is the same visibility gap discussed in the broader argument that high-level aerospace scoreboards can be deeply misleading. Deliveries, revenue, and backlog hide the operational truth. So does an ERP screen that appears complete but lacks real-time execution detail.

    This article explains where ERP works well in aerospace, where it stops at the edge of the shop floor, and what a dedicated execution layer must provide to close the gap.

    What ERP Does Well in Aerospace Manufacturing

    ERP is not the problem. It is simply built for a specific role: coordinating long-horizon planning, finance, and high-level production structures. In a regulated, long-cycle environment like aerospace and defense, those strengths matter.

    Long-horizon planning, MRP, and capacity modeling

    ERP systems excel at describing multi-year programs, long lead-time materials, and aggregate capacity. They provide:

    • Material Requirements Planning (MRP) across complex bills of material (BOMs) and multi-tier supply chains.
    • Rough-cut capacity planning that matches demand to high-level resource availability over weeks, months, and years.
    • Forecasting and scenario planning for new programs, rate increases, or design changes.

    For aircraft structures, engines, avionics, and space hardware, this strategic view is essential. Long lead-time components, export-controlled materials, and single-source suppliers all have to be modeled and committed well before work starts on the floor.

    Financial integration, costing, and contract structures

    Aerospace programs live and die on their financial architecture. ERP is the system that ties operational plans to contracts and cash:

    • Cost collection and allocation across work breakdown structures and cost accounts.
    • Contract and project accounting for government and commercial programs, including earned value and milestone billing.
    • Invoicing, revenue recognition, and margin analysis at the program, lot, or configuration level.

    This is also how OEMs and prime contractors coordinate with suppliers at a commercial level. Purchase orders, receipts, and invoice matching all run through ERP, providing the financial backbone that external auditors expect.

    Baseline routings and high-level work orders

    ERP holds the nominal view of how work should flow through the factory:

    • Standard routings that define major operations and work centers.
    • Planned work orders that describe which assemblies will move through those routings and when.
    • Reference to manufacturing and engineering data such as part numbers, revisions, and configuration families.

    This level of structure is valuable for planning labor, synchronizing with MRP, and giving finance a way to understand progress. But it is not the level where aerospace execution actually lives.

    Where ERP Stops: The Reality Gap on the Shop Floor

    The further you get toward the point of work, the more visible ERP’s limitations become. The model in ERP is abstract and relatively static. The factory is not.

    Dynamic work sequencing and real-time priorities

    On any given shift, supervisors and planners are constantly re-sequencing work:

    • Pulling forward operations to protect a delivery milestone.
    • Re-routing work around a down machine, unavailable tooling, or a blocked inspection station.
    • Adjusting priorities when a hot unit arrives from a customer or a critical test slot opens up.

    ERP can represent planned sequences and due dates. It is not designed to act as a live dispatch system that adapts minute by minute as constraints change. The result is a disconnect: what the ERP schedule says should be running and what the shop is actually running are often different, with the true logic living in local knowledge, emails, and paper travelers.

    Detailed operation status, holds, and disruptions

    ERP typically records status at the work order or major operation level: released, in process, complete. Aerospace execution requires far more granularity:

    • Which specific unit is at which station right now?
    • Is it actively being worked, waiting on material, or queued behind another lot?
    • Is it on hold for an engineering issue, a suspected non-conformance, or a missing certification?

    Capturing this level of status and context in ERP would mean turning a transactional database into a high-frequency event system. Most organizations choose not to do that, so they push this detail into travelers, local spreadsheets, or an MES-like tool, if one exists. The consequence: central systems show progress, but not the reasons behind delay or instability.

    Granular traceability at the component and lot level

    Aerospace programs demand deep traceability—not just of finished assemblies, but of individual components, lots, and process steps:

    • Which exact hardware, material lots, and special processes are embedded in a serial-numbered unit?
    • Which technician performed a specific operation, with which calibrated tools and which revision of the work instruction?
    • How do you traverse that chain quickly when a supplier issue or field event triggers a containment?

    ERP may be able to store some of this information, but doing so at the resolution and volume required for modern aerospace quickly becomes impractical. The data model and user experience are not optimized for capturing and navigating execution detail at the point of work.

    How the Gap Shows Up in Day-to-Day Operations

    The gap between ERP’s model and factory reality is not theoretical. It appears in the specific workarounds aerospace teams rely on just to run the day.

    Shadow systems: spreadsheets and whiteboards

    One of the clearest indicators that ERP is not enough is how much critical information lives outside of it:

    • Supervisors maintain Excel boards with their own view of WIP, priorities, and constraints.
    • Production meetings rely on printed reports annotated by hand to reflect the real situation.
    • Cells and lines track status on whiteboards that are updated between shifts.

    These shadow systems are a rational response to a real need: people require a fast, flexible, live representation of work that ERP does not offer. But they create risk. They are not controlled, not audited, and not visible to the rest of the organization.

    Disconnected quality, inspection, and non-conformance workflows

    In an AS9100 environment, quality and inspection processes must be tightly linked to execution. Yet they often run as parallel flows:

    • Inspection plans and checklists in point solutions or PDFs.
    • Non-conformance reports (NCRs) in a separate QMS, with manual reference to work orders and serials.
    • Rework instructions and concessions communicated via email or manual document routing.

    ERP might record the existence of an NCR or a rework order, but not the detailed path that unit took through quality decisions, nor the exact data needed to prove compliance in an audit. This fragmentation makes root cause analysis, escape investigations, and customer reporting slow and error-prone.

    Manual status chasing for internal and customer reporting

    Program reviews and customer status updates expose the underlying data problem. To answer seemingly basic questions—“Which units are at risk?” “What is blocking this delivery?” “How many hours of rework did we incur this month?”—teams often resort to manual status chasing:

    • Walking the floor to visually confirm where hardware is.
    • Calling or messaging supervisors and planners to reconcile discrepancies.
    • Assembling one-off slides that combine ERP data with locally maintained trackers.

    This is precisely the pattern the industry sees when external scoreboards like deliveries and backlog are treated as truth while the execution system itself remains opaque. The same misalignment exists inside many factories: summary metrics in ERP look fine, but the mechanisms producing them are fragile.

    Why ERP Extensions Rarely Solve Execution

    Many aerospace organizations attempt to close this gap by adding customizations or satellite modules onto ERP. The intent is reasonable—extend the system you already have—but structural constraints get in the way.

    Architectural constraints of transactional systems

    ERP architectures are optimized for transaction integrity and financial correctness, not for capturing every event happening on the shop floor. Pushing detailed execution into ERP creates challenges:

    • High-frequency status updates can strain performance and licensing models.
    • Complex, stateful workflows are difficult to represent with generic transaction tables.
    • User interfaces built for planners and accountants are not ideal for operators on the line.

    The result is often a partial implementation: a few extra fields, a couple of custom screens, and still a heavy reliance on external trackers for the real work.

    Config complexity and variant-rich aerospace products

    Aerospace hardware is highly configurable. Block points, customer-specific options, retrofits, and engineering changes all intersect on the same physical units. Representing that complexity at the execution level requires:

    • Fine-grained configuration control down to the unit and operation.
    • Dynamic work instructions that reflect the exact configuration in front of the operator.
    • Ability to split and merge work, track partial completions, and handle deviations without losing traceability.

    ERP is typically built around products, BOMs, and routings—not around an ever-changing, unit-specific execution graph. As configuration complexity grows, the gap between ERP’s static model and reality widens.

    Audit and certification needs beyond standard ERP data models

    AS9100, customer flow-downs, and regulatory requirements (e.g., export control, special processes, safety-critical components) demand an auditable record that goes beyond standard ERP fields:

    • Who performed each step, with which qualifications, at what time.
    • Which specific procedures, drawings, and revisions were in force.
    • How non-conformances, escapes, and corrective actions were identified and resolved.

    Trying to retrofit this level of detail into ERP often results in overgrown, hard-to-maintain customizations that still don’t match how work is actually performed. Audits then become reconstruction exercises instead of straightforward queries on a clean execution history.

    Defining the Aerospace Execution Layer

    To resolve this, organizations increasingly recognize the need for a distinct—but tightly connected—execution layer. This is not a competing system of record for finance and planning. It is the operational environment that lives between plan and reality.

    Characteristics of a system that lives between plan and reality

    A true aerospace execution layer has several defining properties:

    • Plan-aware but not plan-bound: It understands work orders, routings, and configurations from ERP, but allows dynamic re-sequencing, holds, and path changes based on actual conditions.
    • Event-centric: It records what really happens at the point of work—starts, pauses, completions, inspections, NCRs, and signoffs—as a time-stamped stream of events.
    • Unit-level context: It follows individual serials or lots through their unique paths, rather than just aggregating by part number or routing.

    This is the layer where execution rules and operational reality are reconciled in real time.

    Real-time WIP tracking, operation context, and user workflows

    Practically, an execution platform must allow teams to see and control work in process (WIP) at a level ERP can’t provide:

    • Where every unit is, which operation it is on, and what is blocking it, updated continuously.
    • Operator-guided workflows that present the right instructions, data capture, and checks at the right step.
    • Visualizations of queues, constraints, and aging WIP for supervisors and program managers.

    Instead of reconstructing status from multiple sources, the execution layer becomes the single operational picture of the factory—fed by events at the point of work and aligned with the plan in ERP.

    Embedded traceability and configuration control at the point of work

    Traceability and configuration control are most robust when they are embedded in how work is done, not layered on afterward. In an execution layer, that means:

    • Capturing serials, material lots, and process parameters as part of the operator’s normal workflow.
    • Ensuring only the correct, released instructions and data are available for the specific configuration in front of the operator.
    • Automatically building a complete genealogy and event history as a byproduct of execution, not a separate data-entry task.

    This is the difference between being audit-ready by default and having to assemble evidence from ERP logs, shared drives, and paper packets whenever a customer or regulator asks.

    Integrating ERP with a Connected Execution Platform

    None of this works if ERP and the execution layer are isolated. The value comes from clear boundaries and deliberate integration, not from trying to make one system do every job.

    Data boundaries: what stays in ERP versus the execution layer

    A clean architecture assigns responsibilities explicitly:

    • ERP remains the system of record for contracts, orders, BOMs, routings, inventory positions, and financial transactions.
    • The execution layer becomes the system of reality for WIP state, operation history, quality events, operator interactions, and unit-level genealogy.

    The two are synchronized, but they do not duplicate each other. ERP doesn’t need every operator keystroke. The execution platform doesn’t need to manage accounts receivable.

    Event-driven updates from shop floor to planning systems

    Instead of batch uploads or manual status pushes, the execution layer should feed ERP using event-driven integration:

    • When operations complete, ERP receives the necessary confirmations for backflush, cost collection, and schedule updates.
    • When holds or major deviations occur, ERP and planning tools get signals that a plan needs to be re-evaluated.
    • When units move across key milestones, program-level metrics refresh automatically.

    This approach preserves ERP’s role as the planning and financial backbone while ensuring its view of progress is anchored in actual execution data.

    Synchronizing BOM, routing, and configuration data

    For aerospace, configuration discipline is non-negotiable. Integration must ensure:

    • Approved BOMs, routings, and effectivity rules flow from ERP and engineering systems into the execution layer in a controlled manner.
    • Changes are versioned, with clear cut-in points so that units in process do not drift into ambiguous states.
    • The execution layer can enrich that structure with unit-specific context (e.g., concessions, unique serials, local rework paths) without breaking the underlying configuration logic.

    This is also where a practical digital thread begins to emerge: the ability to follow a configuration from engineering intent through planning, execution, test, and delivery without losing continuity.

    Example integration patterns for aerospace manufacturers

    In practice, aerospace manufacturers often adopt patterns such as:

    • Work-order centric integration: ERP creates and owns orders; the execution layer owns detailed steps and status, sending back completions and key quality flags.
    • Serial-centric integration: Each serial number becomes the common key across ERP, execution, test, and field systems, allowing clear traceability across the lifecycle.
    • Milestone signaling: The execution layer drives program milestones (e.g., mate, power-on, test complete) that ERP and reporting tools consume as the basis for progress and billing.

    These patterns align with aerospace realities: long cycles, complex assemblies, and the need to reconcile financial, operational, and regulatory views of the same hardware.

    Choosing the Right System Roles for a Regulated Environment

    In an AS9100-governed organization, architecture choices are also compliance choices. How you assign system roles influences your ability to demonstrate control, traceability, and data integrity.

    Aligning with AS9100 and customer flow-down requirements

    AS9100 emphasizes documented processes, controlled records, and clear responsibility for quality. A well-designed split between ERP and execution supports this by:

    • Making ERP the authoritative source for approved part numbers, routings, and high-level planning.
    • Using the execution layer to capture how those processes were actually executed, including deviations, approvals, and verifications.
    • Ensuring that customer and regulatory requirements are traceable from specification through to the specific steps and checks performed on each unit.

    This reduces the gap between procedure and practice, which is where many audit findings originate.

    Ensuring data integrity and auditability across systems

    Having multiple systems does not have to mean fragmented data. It can, if done well, increase auditability:

    • ERP holds stable master data and financial transactions, with strong change control.
    • The execution layer produces a high-resolution record of events, approvals, and measurements tied to specific units.
    • Integration provides a clear chain of custody: it is always visible how plan data was used, how execution data was produced, and how the two informed each other.

    This architecture also supports selective disclosure: you can give customers or regulators deep visibility into execution history without exposing internal financial structures.

    How platforms like Connect 981 complement, not replace, ERP

    The industry’s direction is not to abandon ERP, but to surround it with systems that make its information meaningful in real time. Platforms like Connect 981 operate in this execution space:

    • Taking the plan, configuration, and contractual context from ERP.
    • Providing the live, unit-level picture of work, quality, and traceability that ERP cannot practically own.
    • Feeding clean, structured execution signals back into planning, reporting, and decision-making layers.

    For aerospace manufacturers, the question is less “Can ERP be made to do everything?” and more “How do we design a connected execution system where ERP, the shop floor, and quality all see the same reality?” The answer lies in embracing a dedicated execution layer that complements ERP, closes the visibility gap, and makes the high-level scoreboard reflect the real state of the system underneath.

  • MES vs ERP vs Reality: Where Aerospace Execution Actually Lives

    MES vs ERP vs Reality: Where Aerospace Execution Actually Lives

    In many aerospace factories, people talk about ERP and MES as if they are interchangeable. On whiteboards, the stack looks clean: ERP plans, MES executes, the shop floor produces. But when programs come under pressure, the reality rarely matches the diagram.

    Production managers still chase paper travelers. Quality teams rebuild traceability for audits. Engineering changes arrive mid-build and ricochet through email and spreadsheets. The scoreboard metrics—deliveries, backlog, revenue—look like progress, but they hide how fragile execution has become. This is the same visibility gap explored in the hub article The Aerospace Scoreboard Is Lying to You: the space between what systems say should be happening and what is actually happening now.

    For teams putting this topic into daily operation, execution systems for aerospace manufacturing, shop floor execution control, ERP, MES, and PLM integration paths help connect the concept to traceability, work-order reality, and audit-ready evidence.

    The same operating model also depends on a connected execution platform, Connect 981’s aerospace execution solutions, real aerospace execution examples, Connect 981’s aerospace operations guidance, especially when decisions have to move across quality, production, suppliers, and program leadership without losing context.

    This article uses the ISA‑95 lens to separate ERP, MES, and a modern execution layer in regulated aerospace environments. The goal is not to declare winners, but to clarify where work really lives—especially the parts that matter most for AS9100, FAA, and EASA oversight.

    Why System Boundaries Are Blurry in Aerospace Factories

    How legacy deployments shaped current ERP/MES expectations

    Most aerospace organizations did not design their digital architecture from scratch. They accumulated it. ERP arrived to unify finance, contracts, and basic production planning. Years later, MES or homegrown shop-floor systems were layered in to address specific pain—often in final assembly, special processes, or test.

    Those early MES deployments were usually scoped narrowly: capture some production data, dispatch operations to machines, produce basic OEE. Over time, additional requirements piled on: electronic work instructions, shop floor non-conformances, basic genealogy, sometimes electronic signoffs. Each plant, and sometimes each program, evolved its own flavor of “MES.” The result is a patchwork where the same acronym describes very different realities.

    Different interpretations of MES across plants and suppliers

    Ask five aerospace suppliers to define MES and you will hear five different answers:

    • A scheduling and dispatching tool for CNC machines
    • A traveler and electronic work instruction system
    • A data historian and OEE dashboard
    • An electronic quality record and non-conformance log
    • A catch-all layer between ERP and the line

    All of these are partially true. None of them describe the full execution reality. For a complex assembly like an aircraft structure or propulsion system, critical information often lives outside MES entirely: email approvals, spreadsheet-based configuration matrices, PDF drawings in shared drives, supplier certifications in separate portals.

    When MES is defined locally by what one site needed at the moment of purchase, it becomes difficult to reason about its role in the broader ISA‑95 architecture.

    The impact of customizations on architectural clarity

    To close gaps, aerospace organizations frequently customize MES and ERP. Over time, these customizations blur originally clear boundaries:

    • ERP instances that hold detailed operation-level routing logic and shop-floor rules
    • MES instances that reach up into demand management, scheduling, and even basic contract attributes
    • Custom middleware or scripts that move partial data in ways nobody fully documents

    Short term, these decisions feel pragmatic: meet a program milestone, satisfy a particular customer requirement, pass an audit. Long term, they erode architectural clarity. When no one can say with confidence which system is the “source of truth” for a given decision—configuration, revision, process spec, inspection requirement—execution relies on tribal knowledge.

    That lack of clarity is precisely what ISA‑95 was meant to prevent. In aerospace, we need to revisit those boundaries with the realities of regulated, high-mix, manual-heavy production in mind.

    ERP’s Role Through the Lens of ISA‑95

    Level 4: planning, scheduling, and financial alignment

    In ISA‑95 terms, ERP operates primarily at Level 4: business planning and logistics. In aerospace, this translates to:

    • Long-horizon production planning for programs and platforms
    • Master scheduling across lines, cells, and suppliers
    • Material requirements planning (MRP) and procurement
    • Costing, revenue recognition, and financial reporting
    • Contract-level delivery dates and penalties

    ERP is the system that holds the official promise to the market: how many units will be delivered, when, under which contract, and at what cost structure. It must integrate deeply with finance, contracts, and supply chain.

    Master data, contracts, and high-level orders

    ERP also carries critical master data:

    • Part and assembly identifiers
    • Customer contracts and line items
    • Approved suppliers and lead times
    • High-level routings and work centers

    In aerospace, these data objects are tightly coupled to regulatory and customer requirements. For example, an ERP work order for a flight-critical assembly implicitly encodes configuration baselines, contractual acceptance criteria, and delivery milestones.

    However, ERP only represents intended work. It does not know the exact sequence of actions technicians will perform, the specific tools and gauges they will use, or the real-time status of each operation on the floor.

    Why ERP is not designed for second-by-second execution detail

    ERP systems were never meant to operate at the granularity of real-time execution. They are optimized for transactional consistency and financial control, not for sub-minute event streams, sensor data, or technician interactions.

    Trying to force ERP into a second-by-second execution role usually creates friction:

    • Slow user interfaces and complex screens on the shop floor
    • Limited support for offline or constrained environments
    • Difficulty handling rapid configuration changes at the operation level
    • Performance challenges with high-frequency data like test results or IIoT events

    For regulated aerospace programs, the risk is more than inconvenience. If ERP becomes the de facto execution system, teams start to work around it with shadow spreadsheets and parallel workflows. That shadow layer is where traceability and configuration control begin to fracture.

    What MES Traditionally Covers—and What It Doesn’t

    Typical MES functions: dispatching, data collection, OEE

    Traditional MES tools sit at ISA‑95 Levels 3 and 2, close to the line. In aerospace factories, common MES capabilities include:

    • Dispatching work orders and operations to workstations or machines
    • Tracking basic production status (started, in progress, completed)
    • Collecting production counters, cycle times, and machine states for OEE
    • Capturing operator logins and simple electronic signoffs
    • Integrating with equipment for automatic data capture in highly automated cells

    These functions are important, but they reflect a manufacturing world where operations are relatively repeatable, tact times are stable, and automation dominates. Many aerospace environments look very different.

    Support for automated versus manual operations

    In aerospace, a significant share of value-added work is manual or semi-manual:

    • Complex composite layups
    • Detail assembly and sub-assembly integration
    • Wiring harness installation
    • Structural drilling, fastening, and sealing
    • Functional testing and troubleshooting

    Traditional MES excels when there is a tight coupling to equipment states and well-defined cycles. It struggles when a single operation can take hours or days, with dozens of micro-decisions, engineering clarifications, and quality checks along the way.

    As a result, many aerospace sites keep MES usage shallow for manual work: start/stop timestamps, a few data fields, and a signoff. The real context—engineering dispositions, process deviations, temporary repairs, test adjustments—lives elsewhere.

    Gaps in supplier collaboration and end-to-end traceability

    Another structural gap is that MES is often plant-centric. It tracks what happens inside a site boundary, not across the aerospace supply chain. Yet end-to-end traceability is precisely what auditors and regulators expect:

    • Material and process genealogy from raw stock to final assembly
    • Supplier certifications and special process qualifications
    • Change histories across design, planning, and execution
    • Linkage between non-conformances, corrective actions, and delivered units

    MES rarely owns the full picture. Supplier data arrives through portals, emails, and PDFs. Engineering changes come from PLM or configuration management tools. Quality events may live in separate QMS platforms. Without an explicit execution layer designed to stitch these flows together, aerospace manufacturers rely on people to create the digital thread manually.

    Reality Checks from Aerospace Programs

    Where paper travelers still dominate critical processes

    Despite significant investments in ERP and MES, paper travelers remain common in aerospace environments, including on critical assemblies. Reasons include:

    • Legacy processes never fully migrated into digital systems
    • Complex rework flows that are easier to annotate by hand
    • Supplier work packages that arrive in paper or PDF-only formats
    • Lack of confidence that the digital system reflects the latest engineering intent

    Every time a process drops to paper, live traceability becomes reconstruction. After-the-fact data entry is error-prone and rarely captures the full context of what occurred at the point of work.

    Workarounds for handling engineering changes on the line

    Engineering changes are a normal part of aerospace programs, especially early in the lifecycle. The problem is how they are handled operationally. Common patterns include:

    • Emailing revised drawings or work instructions to supervisors
    • Printing temporary instructions and stapling them to travelers
    • Maintaining local spreadsheets that map part numbers to special instructions
    • Relying on toolbox talks and shift meetings to communicate changes

    Rarely is there a single system that understands: this tail number, at this station, is being built under this exact configuration and deviation set. ERP knows the contract. MES knows the base routing. PLM knows the design change. The line knows the workaround. Nobody has the integrated view.

    How quality and non-conformance workflows often sit outside MES

    In many aerospace organizations, quality systems evolved independently from MES:

    • Non-conformance and MRB processes run in a QMS or separate tool
    • Inspection results are recorded in standalone databases or forms
    • Corrective actions and audits are tracked in yet another system

    When an NC is raised on the floor, the technician may log it in a QMS, then manually backfill MES status, then notify planning by email. Each handoff dilutes the connection between the physical part, the work performed, the digital record, and the final configuration delivered to the customer.

    Under normal conditions, these gaps are survivable. Under stress—rate increases, design changes, regulatory scrutiny—they become the difference between stable throughput and systemic gridlock.

    Defining a Modern Aerospace Execution Layer

    Bridging ERP plans and MES/plant-floor signals

    A modern aerospace execution layer is not a rebranded MES or ERP module. It is a dedicated layer that:

    • Consumes plans and constraints from ERP (orders, routings, dates, capacity assumptions)
    • Connects to MES, IIoT, test systems, and manual reporting channels for real-time status
    • Maintains a high-fidelity view of work-in-progress (WIP) by unit, assembly, and configuration
    • Surfaces deviations, delays, and risk in time for action, not post-mortem reporting

    In the language of the hub narrative, it is the layer that makes the aerospace “scoreboard” honest. Instead of relying solely on deliveries and backlog, it exposes execution capability and constraint.

    Embedding configuration control and digital thread awareness

    For aerospace, configuration control is non-negotiable. An execution layer must treat configuration as a first-class concept, not metadata:

    • Binding specific engineering baselines, deviations, and waivers to each unit
    • Ensuring work instructions reflect the correct configuration at the moment of execution
    • Recording which configuration was actually used when work occurred
    • Maintaining a navigable digital thread from requirement to delivered hardware

    This is more than attaching a drawing revision to a work order. It requires contextual awareness. When a technician opens a task, the system must understand which configuration applies, what changes are in effect, and which quality controls are mandatory for that specific unit and operation.

    Experience design for technicians, engineers, and quality teams

    A practical execution layer also pays attention to experience:

    • Technicians need clear, current, and unambiguous instructions with minimal navigation overhead
    • Engineers need to introduce changes in a controlled way, with visibility into who is affected and when
    • Quality teams need to see context-rich data around each defect: configuration, process state, environmental factors, and upstream/downstream dependencies

    When these needs are served in a single operational environment, adoption follows. People stop relying on parallel spreadsheets because the system of record is finally aligned with how work actually happens.

    Data Flows Across ERP, MES, and Execution Platforms

    Order, operation, and routing synchronization

    The most fundamental data flow is between ERP and the execution layer:

    • ERP sends order headers, line items, and planned routings
    • The execution layer refines those into executable tasks, sequences, and work packages
    • Changes in planning (reschedules, splits, cancellations) are propagated without losing traceability

    MES may still perform detailed dispatching, especially for automated cells. The key is that the execution layer remains the reference for what work exists, how it is structured, and how it maps back to contracts, configurations, and units.

    Event streams from IIoT, test stands, and inspections

    Aerospace factories generate diverse data streams:

    • Sensor data from environmental controls and curing processes
    • Test stand results and functional verification logs
    • Dimensions and measurements from inspections and metrology
    • Manual confirmations from technicians and inspectors

    Traditional MES may capture some of this, but often in siloed ways. An execution layer should focus on contextualizing events rather than simply storing them. Every data point should be tied to a specific unit, configuration, operation, and point in the process.

    Feeding back status, non-conformance, and genealogy to upstream systems

    Finally, the execution layer becomes the source for downstream and upstream visibility:

    • ERP receives summarized status and milestone completions to keep plans realistic
    • QMS receives structured, context-rich non-conformance and inspection data
    • PLM and configuration management systems receive feedback on how designs behave in production
    • Program teams gain access to unit-level genealogy and build history without interrogating multiple platforms

    The objective is not to replace existing systems of record, but to coordinate them so that the picture of reality is coherent and timely.

    Architecting for Regulated Supply Chains

    Supporting AS9100, FAA, and EASA evidence requirements

    Regulators and customers increasingly expect that aerospace organizations can produce evidence, not narratives. That evidence spans:

    • Who performed each operation, under which qualification
    • Which tools, materials, and processes were used
    • How deviations and waivers were controlled
    • How corrective actions were implemented and verified

    An execution layer simplifies this by making compliance a natural byproduct of doing the work, not a separate documentation exercise. When data capture is embedded in execution, audit readiness becomes continuous rather than episodic.

    Supplier visibility and collaboration across system boundaries

    Aerospace supply chains are multi-tier and global. No single organization controls every system edge. To achieve real execution visibility across that network, the architecture must:

    • Respect that each supplier will keep its own ERP, MES, and QMS stack
    • Provide a common way to exchange execution-relevant data: status, certifications, genealogy
    • Support secure, selective sharing of data to maintain confidentiality while enabling oversight

    This is where a connectivity-focused execution platform becomes critical. It acts as a collaboration surface across organizations without demanding that everyone adopt the same monolithic system.

    Why platforms like Connect 981 emphasize connectivity over monoliths

    A monolithic approach—trying to force ERP to be MES, or MES to be the only execution layer—breaks down in complex aerospace ecosystems. The reality is heterogeneous: different plants, different suppliers, different legacy systems.

    Platforms in the Connect 981 category emphasize connection and orchestration over replacement. They sit between planning and the shop floor, integrate with existing tools, and provide a coherent operational picture across programs and partners. They are less about owning every transaction and more about ensuring that, when the industry looks beyond the scoreboard, it can finally see how execution is truly performing.

    For aerospace organizations facing rising expectations, tighter regulatory scrutiny, and more complex supply chains, the question is no longer “ERP or MES?” It is whether there is a deliberate execution layer that turns fragmented systems into a controllable, auditable whole.

  • Digital Thread for Aerospace Manufacturing: From Buzzword to Practical Implementation

    Digital Thread for Aerospace Manufacturing: From Buzzword to Practical Implementation

    Digital thread comes up in nearly every aerospace strategy deck. Diagrams show elegant loops from concept to design to manufacturing to MRO. But on most programs, the reality still looks like this: PLM and ERP are reasonably structured, execution happens in a mix of travelers, spreadsheets, and tribal knowledge, and quality and compliance teams stitch the story together after the fact.

    To make sense of the gap, you first have to recognize that aerospace is not a scoreboard business. Deliveries, backlog, and revenue are lagging indicators of something more fundamental: how well you understand and control execution across internal factories and suppliers. That execution layer is where a real digital thread either exists or quietly breaks. This article explains what digital thread in aerospace actually is, how it fails in practice, and how a connected execution layer—of the kind discussed in the underlying aerospace execution story—turns the idea into something operational.

    For teams putting this topic into daily operation, Connect 981’s aerospace execution solutions help connect the concept to traceability, work-order reality, and audit-ready evidence.

    For teams putting this topic into daily operation, execution systems for aerospace manufacturing, shop floor execution control help connect the concept to traceability, work-order reality, and audit-ready evidence.

    The same operating model also depends on a connected execution platform, Connect 981’s aerospace operations guidance, practical aerospace operations FAQs, closing the Engineering Change Execution Gap, especially when decisions have to move across quality, production, suppliers, and program leadership without losing context.

    Why Digital Thread Matters More in Aerospace Than Anywhere Else

    Almost every manufacturing sector talks about traceability and data continuity. Aerospace, defense, and space hardware production live under constraints that make digital thread more than a nice-to-have. It is directly tied to safety, certification, and program survivability over decades.

    Long Program Lifetimes and Frequent Configuration Changes

    Aircraft, spacecraft, and mission systems often stay in service for 20–40 years. Over that lifetime, designs evolve, part numbers change, suppliers shift, and regulatory expectations move. A single airframe or propulsion unit may embody hundreds of engineering change notices (ECNs), service bulletins, and retrofit campaigns.

    Without a connected data story—who built what, using which configuration, under which process, at which revision—operators and OEMs face two recurring problems:

    • Unclear baselines: You know a tail number or serial number, but not which exact configuration and concessions apply to the physical asset in front of you.
    • Expensive retro-discovery: Every modification or investigation becomes a mini-forensic effort across PLM, ERP, quality systems, and archived travelers.

    A functioning digital thread keeps configuration intent and as-built reality aligned over that entire lifecycle.

    Safety-Critical Hardware and Regulatory Scrutiny

    Aerospace hardware is designed, built, and maintained under tight regulatory oversight from authorities such as FAA and EASA, and in defense environments under additional customer and export constraints. AS9100, DO-178/254 (for software and electronics), and program-specific requirements all converge on the same expectation: you must be able to demonstrate how a given part or assembly was produced, inspected, and controlled.

    This is not just about storing records. Regulators and customers increasingly expect that records are coherent—that configuration, process, and quality data can be tied together quickly and unambiguously. That is only possible when the digital thread connects the systems where these data originate, not just where they are archived.

    Complex, Multi-Tier Supplier Ecosystems

    Modern aerospace programs depend on deep, multi-tier supply chains. Critical hardware, from structural components to flight-critical electronics to propulsion subsystems, is often designed and produced across multiple organizations and regions.

    In practice, this means that no single company controls the entire data landscape. Part genealogies are fragmented, revision states differ by partner, and the intent encoded in OEM specifications may be implemented through several layers of process translation. A robust digital thread creates a shared operational picture of configuration and evidence, even when the underlying production network is distributed.

    Defining Digital Thread in Practical Aerospace Terms

    Conceptually, digital thread is the connected flow of data that links requirements, design, manufacturing, testing, delivery, and in-service operations. Practically, in aerospace manufacturing, it comes down to three concrete questions:

    • Are your configuration and process definitions consistently expressed all the way to the point of work?
    • Is the as-built and as-tested record captured as work happens, or reconstructed later?
    • Can you trace a physical part or assembly back through its genealogy, including the suppliers and processes involved?

    From PLM and Engineering Data to Manufacturing Instructions

    Most aerospace programs start with reasonably structured engineering systems. PLM holds product structures, CAD, specifications, and often ECNs. But the digital thread only becomes real when that engineering intent is translated into precise, controlled manufacturing instructions.

    In execution terms, this means:

    • Engineering bill of materials (EBOM) is transformed into a manufacturing bill of materials (MBOM) that reflects how the work is actually done.
    • Process plans and routings are defined with clear operations, resources, inspection points, and required evidence.
    • Work instructions are versioned, structured, and directly traceable back to the underlying engineering definitions.

    The digital thread starts when those links are explicit and managed, not inferred from filenames and email trails.

    Linking BOMs, Routings, and Process Plans to Real Work

    Once the product and process definitions are in place, the next question is whether they remain intact when work is scheduled and executed. In many factories, ERP or planning tools generate work orders and travelers with limited awareness of the full process context.

    A practical digital thread ensures that for each work order or serial number, you can answer:

    • Which configuration baseline does this unit belong to (aircraft block point, engine standard, mission configuration, etc.)?
    • Which revision of the MBOM, routing, and work instructions were in effect when the work was done?
    • Which deviations or waivers were authorized, and by whom?

    This is where an execution-layer system becomes essential. When the production environment knows which configuration and process definition apply to a given serial or lot, the digital thread is preserved down to the station level.

    Capturing Genealogy and As-Built Records Along the Way

    Finally, digital thread requires that you capture what actually happened as work progressed—not just what was planned. For aerospace, this includes:

    • Part genealogy: How subcomponents, materials, and serialized items were combined to form higher-level assemblies.
    • Process evidence: Who performed each step, which tools or equipment were used, and which parameters or measurements were recorded.
    • Quality outcomes: Non-conformances, dispositions, repair actions, and rework paths tied to specific units and operations.

    When these records are linked back to the correct configuration and process definitions, you have an as-built and as-inspected view that can support future investigations, retrofits, and audits without reconstruction.

    Where Digital Thread Breaks in Real Factories

    Most aerospace organizations already own the core systems that could contribute to a digital thread: PLM, ERP, quality systems, document control, and sometimes legacy MES. The failures usually occur in the handoffs and in the execution gap between planning and reality.

    Paper Travelers and Disconnected Work Instructions

    In many regulated factories, the traveler is still the primary arbiter of what work is done. Even when instructions are stored in a document management system, the actual flow on the floor is mediated by printed packets, static PDFs, and operator memory.

    In this model, digital thread breaks because:

    • There is no guarantee the latest revision of instructions is what the operator sees.
    • Process changes may lag execution by days or weeks while existing paper is consumed.
    • Evidence (sign-offs, measurements) is collected on paper and then manually entered, often without robust linking back to configuration and process context.

    The result is a fragmented digital story: engineering lives in PLM, planning in ERP, and actual work in paper stacks.

    Manual Handling of Engineering Change Notices (ECNs)

    Engineering changes are where configuration control either proves itself or collapses. In many organizations, ECNs and change notices propagate through manual workflows: email distributions, spreadsheets to track impacted work orders, and physical stamps on documents.

    This introduces several risks to the digital thread:

    • Incomplete impact analysis: It is unclear which in-progress units and supplier lots are affected.
    • Inconsistent cut-in points: Different teams apply the change at different times, creating hybrid configurations.
    • Poor traceability of decision-making: Why a particular unit was allowed to proceed under an earlier revision is not always documented in a structured way.

    An execution-aware digital thread tightly couples engineering changes to affected work, ensuring that cut-in points and exceptions are visible and enforceable at the point of work.

    Unlinked Quality Data and Non-Conformance Records

    Quality systems in aerospace are often robust on their own terms. Non-conformance reports (NCRs), corrective and preventive actions (CAPA), and concession records are carefully documented. But they are frequently operationally disconnected from the rest of the production data.

    Common patterns include:

    • NCRs recorded with minimal linkage to specific operations, tools, and process versions.
    • Data captured in separate quality databases that are hard to correlate with real-time production status.
    • Trend analysis done periodically, not embedded into daily execution decisions.

    In this environment, the digital thread is incomplete. You can see where defects occurred, but not always the full context that would enable systemic improvement or fast, configuration-specific risk assessments.

    The Execution Layer as the Digital Thread’s Nervous System

    If PLM defines intent and ERP defines plans, the execution layer is where those plans meet reality. In aerospace, this layer is not just a traditional MES; it is a connected operational environment that distributes configuration-aware instructions, captures evidence in real time, and coordinates changes across internal and external production.

    Delivering Current Configuration and Instructions to the Point of Work

    For digital thread to be trustworthy, the station-level view of work must always reflect current configuration intent. That means operators, technicians, and inspectors should never have to guess which instructions or specs apply to the unit in front of them.

    An execution layer enables this by:

    • Binding each work order or serial to a specific configuration baseline, including block points and applicable ECNs.
    • Resolving the correct version of work instructions, drawings, and inspection plans dynamically at the point of use.
    • Preventing work from starting when the required documentation or approvals are not available for the current configuration.

    When this is in place, the digital thread is not abstract. It directly shapes what every operator sees and does.

    Capturing Evidence and Traceability as Work Happens

    The other half of the equation is capturing execution data as a first-class output of production, not as an afterthought. A modern execution layer treats traceability as a byproduct of normal work.

    Operationally, this looks like:

    • Structured electronic sign-offs for each operation tied to user identity, timestamp, and configuration context.
    • Automatic association of tooling, calibration status, and process parameters with the specific units processed.
    • Inline capture of measurements and inspection results, directly linked to the operation, drawing requirement, and serial number.

    This turns the execution layer into the nervous system of the digital thread: every action generates signals that are automatically contextualized and available for quality, engineering, and compliance teams.

    Synchronizing Changes to Suppliers and External Partners

    Because aerospace supply chains are distributed, the digital thread cannot stop at the factory door. Tier-1 and tier-2 suppliers must receive configuration and process intent in a form they can execute reliably, and they must return evidence in a way that integrates into the OEM’s data story.

    A well-designed execution layer supports this by:

    • Providing controlled views of configuration and documentation tailored to each supplier’s scope.
    • Defining how serials, batches, and inspection data should be identified so they can plug back into the OEM’s genealogy model.
    • Making it visible which supplier lots, serials, and concessions are associated with a given aircraft or mission configuration.

    Instead of periodic document drops, the relationship becomes an ongoing exchange of structured execution data, keeping the digital thread continuous across organizational boundaries.

    Digital Thread Across the Regulated Supply Chain

    Creating a digital thread that spans OEMs, integrators, and component suppliers requires both technical and governance decisions. The goal is not one monolithic system, but a shared model of configuration, identification, and evidence exchange.

    Sharing Configuration Intent with Tier-1 and Tier-2 Suppliers

    Most suppliers receive technical data packages (TDPs), drawings, and specifications that define what they must deliver. In a digital-thread-aware ecosystem, those packages are more than document bundles; they are structured configuration definitions.

    This means:

    • Explicit definition of configuration baselines for each part family or assembly.
    • Clear mapping between OEM part numbers and supplier part or model identifiers.
    • Change notifications that specify not just the documents revised, but which configurations, lots, or serial ranges are affected.

    Suppliers in turn align their own process plans and internal travelers to these baselines, so their execution data can be meaningfully integrated back into the OEM’s digital thread.

    Aligning Part Numbering, Revision Control, and Documentation

    One of the most common breakpoints in supply-chain digital thread is inconsistent identification: different part numbers, revision schemes, or document identifiers for what is essentially the same configuration. Over time, this creates ambiguity about which parts are interchangeable or which design standard a delivered lot actually reflects.

    Closing this gap involves:

    • Agreeing on master part identifiers and how local variations map back to them.
    • Defining revision control rules that govern when a new revision is required versus when a change is managed through notes or process updates.
    • Ensuring documentation bundles are machine-referencable (with IDs and metadata) instead of relying solely on filenames and unstructured notes.

    With that foundation, execution data from suppliers—such as lot histories, test results, and concession records—can be joined cleanly with OEM product and configuration models.

    Balancing Data Access with IP and Export Control Constraints

    Digital thread initiatives in aerospace must respect intellectual property boundaries and export control regulations (such as ITAR and EAR in applicable jurisdictions). That does not mean abandoning the thread; it means being precise about which data is shared, with whom, and under what controls.

    Practically, this often leads to architectures where:

    • Each party maintains authoritative records for its own processes and proprietary designs.
    • Only the necessary subset of execution and quality data is exchanged, governed by contracts and regulatory requirements.
    • Interfaces focus on structured identifiers and evidence summaries rather than exposing full internal models.

    The digital thread is thus a federation of trusted connections, not a single shared database.

    Connecting Digital Thread to Compliance and Audits

    For many aerospace organizations, the most immediate, tangible value of digital thread shows up during audits and investigations. When configuration, execution, and quality data are connected, compliance shifts from reconstruction to retrieval.

    Supporting AS9100 Clause Expectations with Live Data

    AS9100 requires control over configuration, documented processes, traceability, and non-conformance handling. A live digital thread anchored in the execution layer helps demonstrate that these are not only defined but also used.

    For example, during an audit you should be able to:

    • Select a serial number and immediately see its configuration baseline, process history, and inspection results.
    • Show how changes were introduced and where cut-in points occurred in production and at suppliers.
    • Trace any non-conformance back to root cause and corrective actions with full context.

    When these views are generated from operational systems rather than offline compilations, auditors gain confidence that the controls are real.

    Linking FAA/EASA Evidence to Underlying Execution Records

    Regulatory authorities often require program-level evidence: certification documents, test reports, reliability data, and service history. These are traditionally maintained as curated packages separate from day-to-day production data.

    A digital thread allows those high-level artifacts to be traced back to the underlying execution and quality records. For instance, a structural test campaign report can be linked to the exact units tested, including their configuration, manufacturing conditions, and any deviations. This depth of traceability becomes vital if issues arise years later and authorities ask how representative prior evidence really was.

    Demonstrating Configuration Control Across Program History

    When incidents or field findings occur, one of the first questions is: Which units are affected? Answering that reliably requires a historic view of configuration, including which changes were applied to which units, under which conditions.

    With a robust digital thread:

    • You can identify population at risk by querying for specific configuration features, supplier lots, or process conditions.
    • You can see how mitigations (service bulletins, retrofits, process changes) were rolled out and verified.
    • You can distinguish between similar-looking units that actually have different risk profiles because of their build histories.

    This is only possible when configuration, genealogy, and execution evidence are consistently linked over time.

    Starting a Digital Thread Journey Without a Big-Bang Project

    Many aerospace organizations hesitate to pursue digital thread initiatives because they appear to require large, multi-system transformations. In practice, some of the most effective programs start by improving execution visibility and traceability for a limited set of high-risk areas, then expand.

    Prioritizing High-Risk Components and Processes

    Instead of trying to connect everything at once, focus on where gaps in the digital thread pose the highest risk or cost. Common starting points include:

    • Flight-critical components with complex routings and multiple special processes.
    • Assemblies with a history of escapes or persistent quality issues.
    • Areas with intensive audit and customer scrutiny, where evidence is currently hard to compile.

    For these scopes, define the minimum viable digital thread: which configuration data must be present at the point of work, what genealogy is required, and which evidence must be captured digitally.

    Instrumenting Critical Operations with Execution Data First

    Progress is fastest when you start where execution and traceability needs are clearest. That typically means:

    • Digitizing work instructions and sign-offs for selected operations.
    • Enforcing revision correctness at station level (no work on outdated instructions).
    • Capturing key measurements, tool IDs, and material traceability inline.

    As these operations become fully traceable, you can extend the same approach to adjacent steps, additional work centers, and eventually suppliers. The digital thread grows organically from a solid execution foundation.

    How Platforms Like Connect 981 Plug into Existing PLM/ERP Landscapes

    Most aerospace organizations will not replace PLM or ERP to achieve digital thread. Instead, they introduce an execution-focused platform that sits between planning and reality, integrating with existing systems while orchestrating work on the shop floor and across suppliers.

    In this model:

    • PLM remains the authoritative source of product and configuration intent.
    • ERP remains the system of record for orders, inventory, and financials.
    • The execution layer (such as Connect 981) becomes the operational backbone that:
      • Resolves the right configuration and work instructions per unit.
      • Guides operators and suppliers through controlled processes.
      • Captures the as-built/as-inspected record as work happens.

    Over time, this architecture aligns with the broader perspective described in the aerospace execution and visibility narrative: moving from scoreboard metrics to an operational understanding of how work actually gets done.

    Digital thread in aerospace is ultimately not a technology label. It is the practical ability to say, for any physical unit in your fleet or backlog: we know exactly what it is, how it was built, and how it has changed over time. That capability emerges when configuration, execution, and evidence are connected through a real execution layer—not just drawn in a lifecycle diagram.